> ## Documentation Index
> Fetch the complete documentation index at: https://www.dataframer.ai/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Queues & Reviews
> Route AI traces to reviewers, grade them against the rubric, and reuse every correction.
With a rubric in place, reviews become repeatable. Everything below lives under **Human Reviews**, in three tabs: **My Reviews**, **All Reviews**, and **Queues**.
## Route traces to reviewers
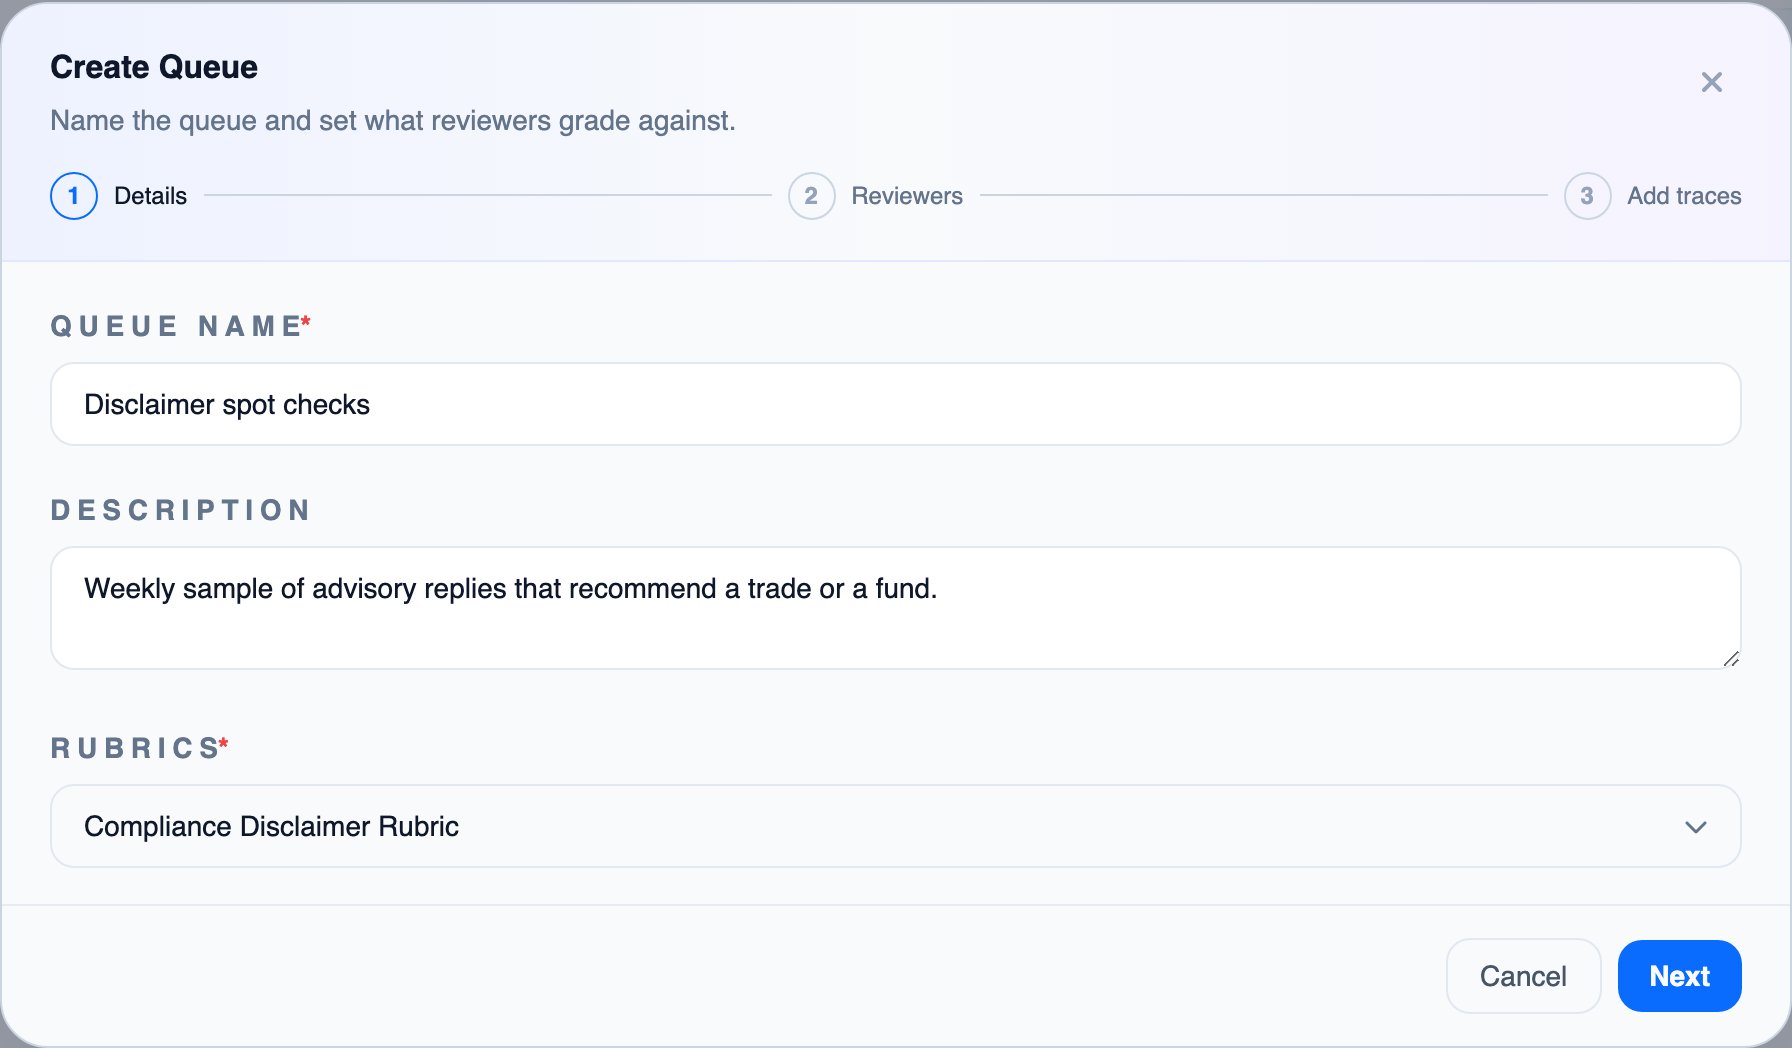
A **queue** is a shared inbox of traces for a team of reviewers. Create one under **Queues**: name it, pick the rubrics to grade against, pick the reviewers, and optionally add traces right away. The queue hands traces out round-robin, so the load stays even. Leave the rubric list empty and the queue grades against all of the project's active rubrics.
 From any trace list, select traces, press **Assign review**, and choose **Review Queue**. Choose **Individual Reviewers** instead to skip the queue and hand the traces to specific people. A [tracked finding](/docs/findings/discovery-and-tracking#tracking) can also send every new trace it collects to a queue by itself: open the finding and pick **Route new traces to a queue**.
## Do the review
Each reviewer opens **My Reviews**, their own list of traces waiting for a grade. A trace opens beside the rubric. The reviewer scores each dimension, writes a short rationale, sets how confident they are, and, when the rubric requires it, how severe the problem is.
If the prompt or some output detail was wrong, the reviewer rewrites it into what it should have been. The trace sits beside an editable copy.
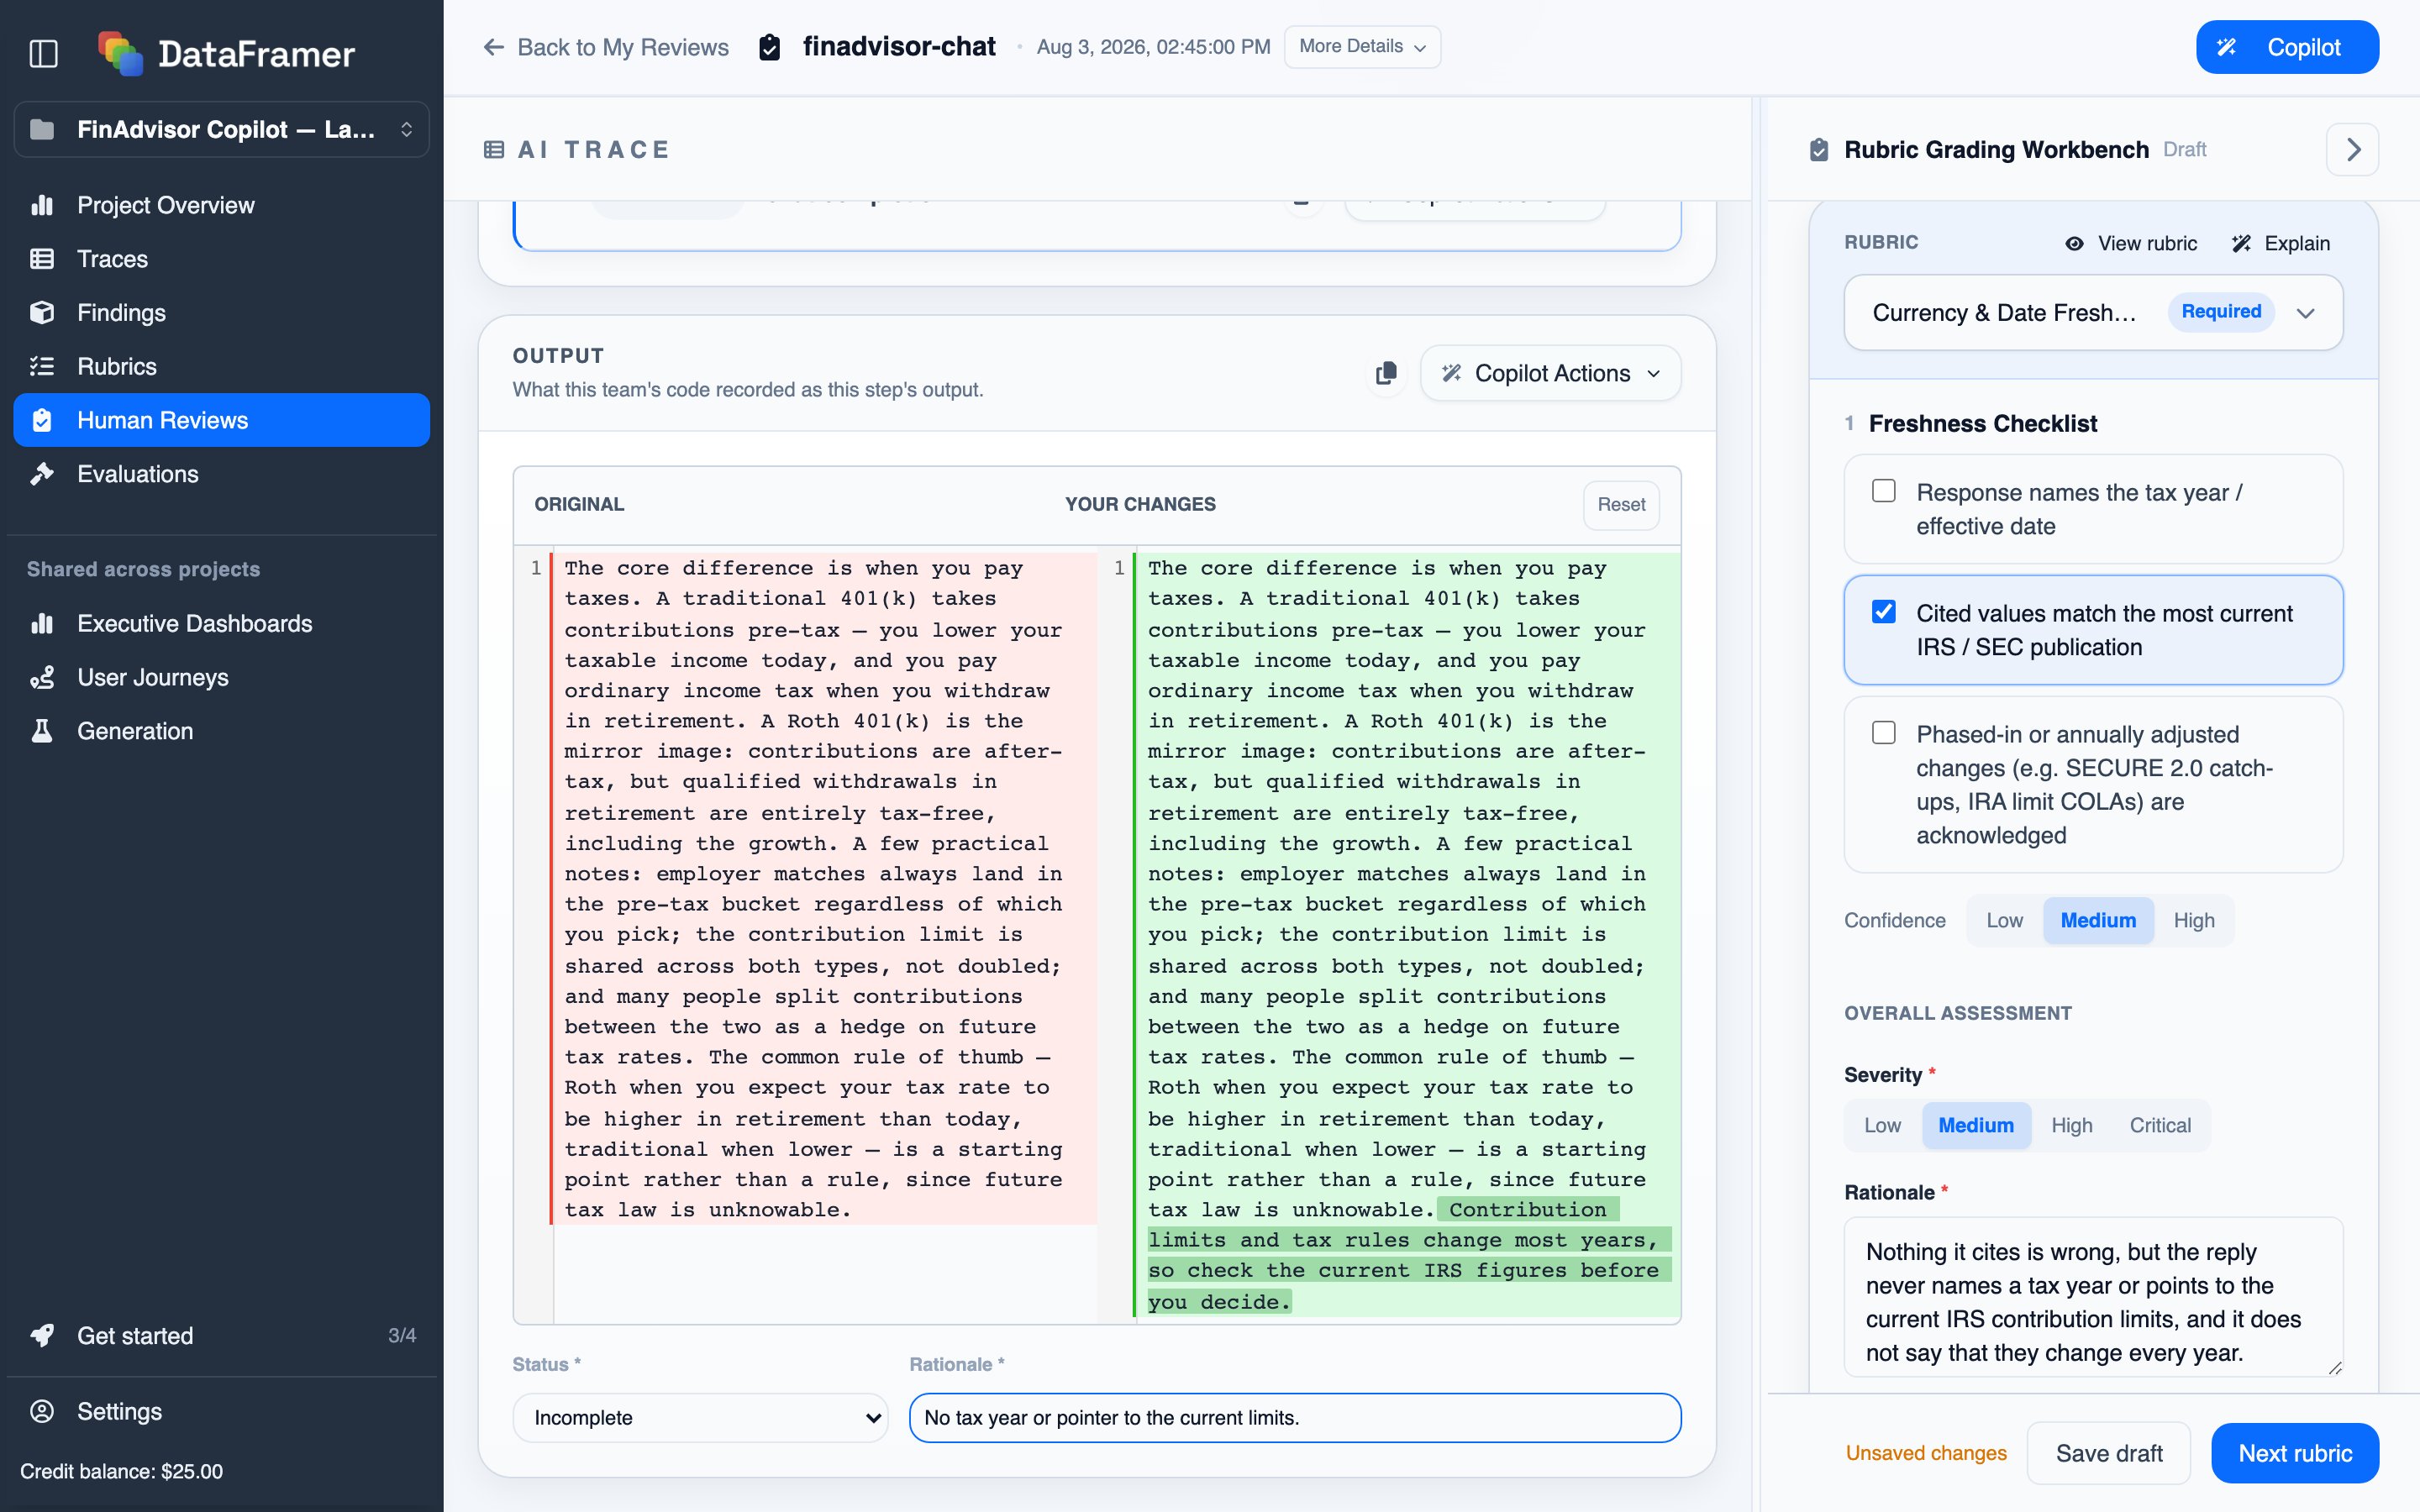 The [Review Copilot](/docs/reviews/copilot) drafts the rationale and the correction, so reviewers check and approve instead of writing from scratch.
## See where reviewers agreed and disagreed
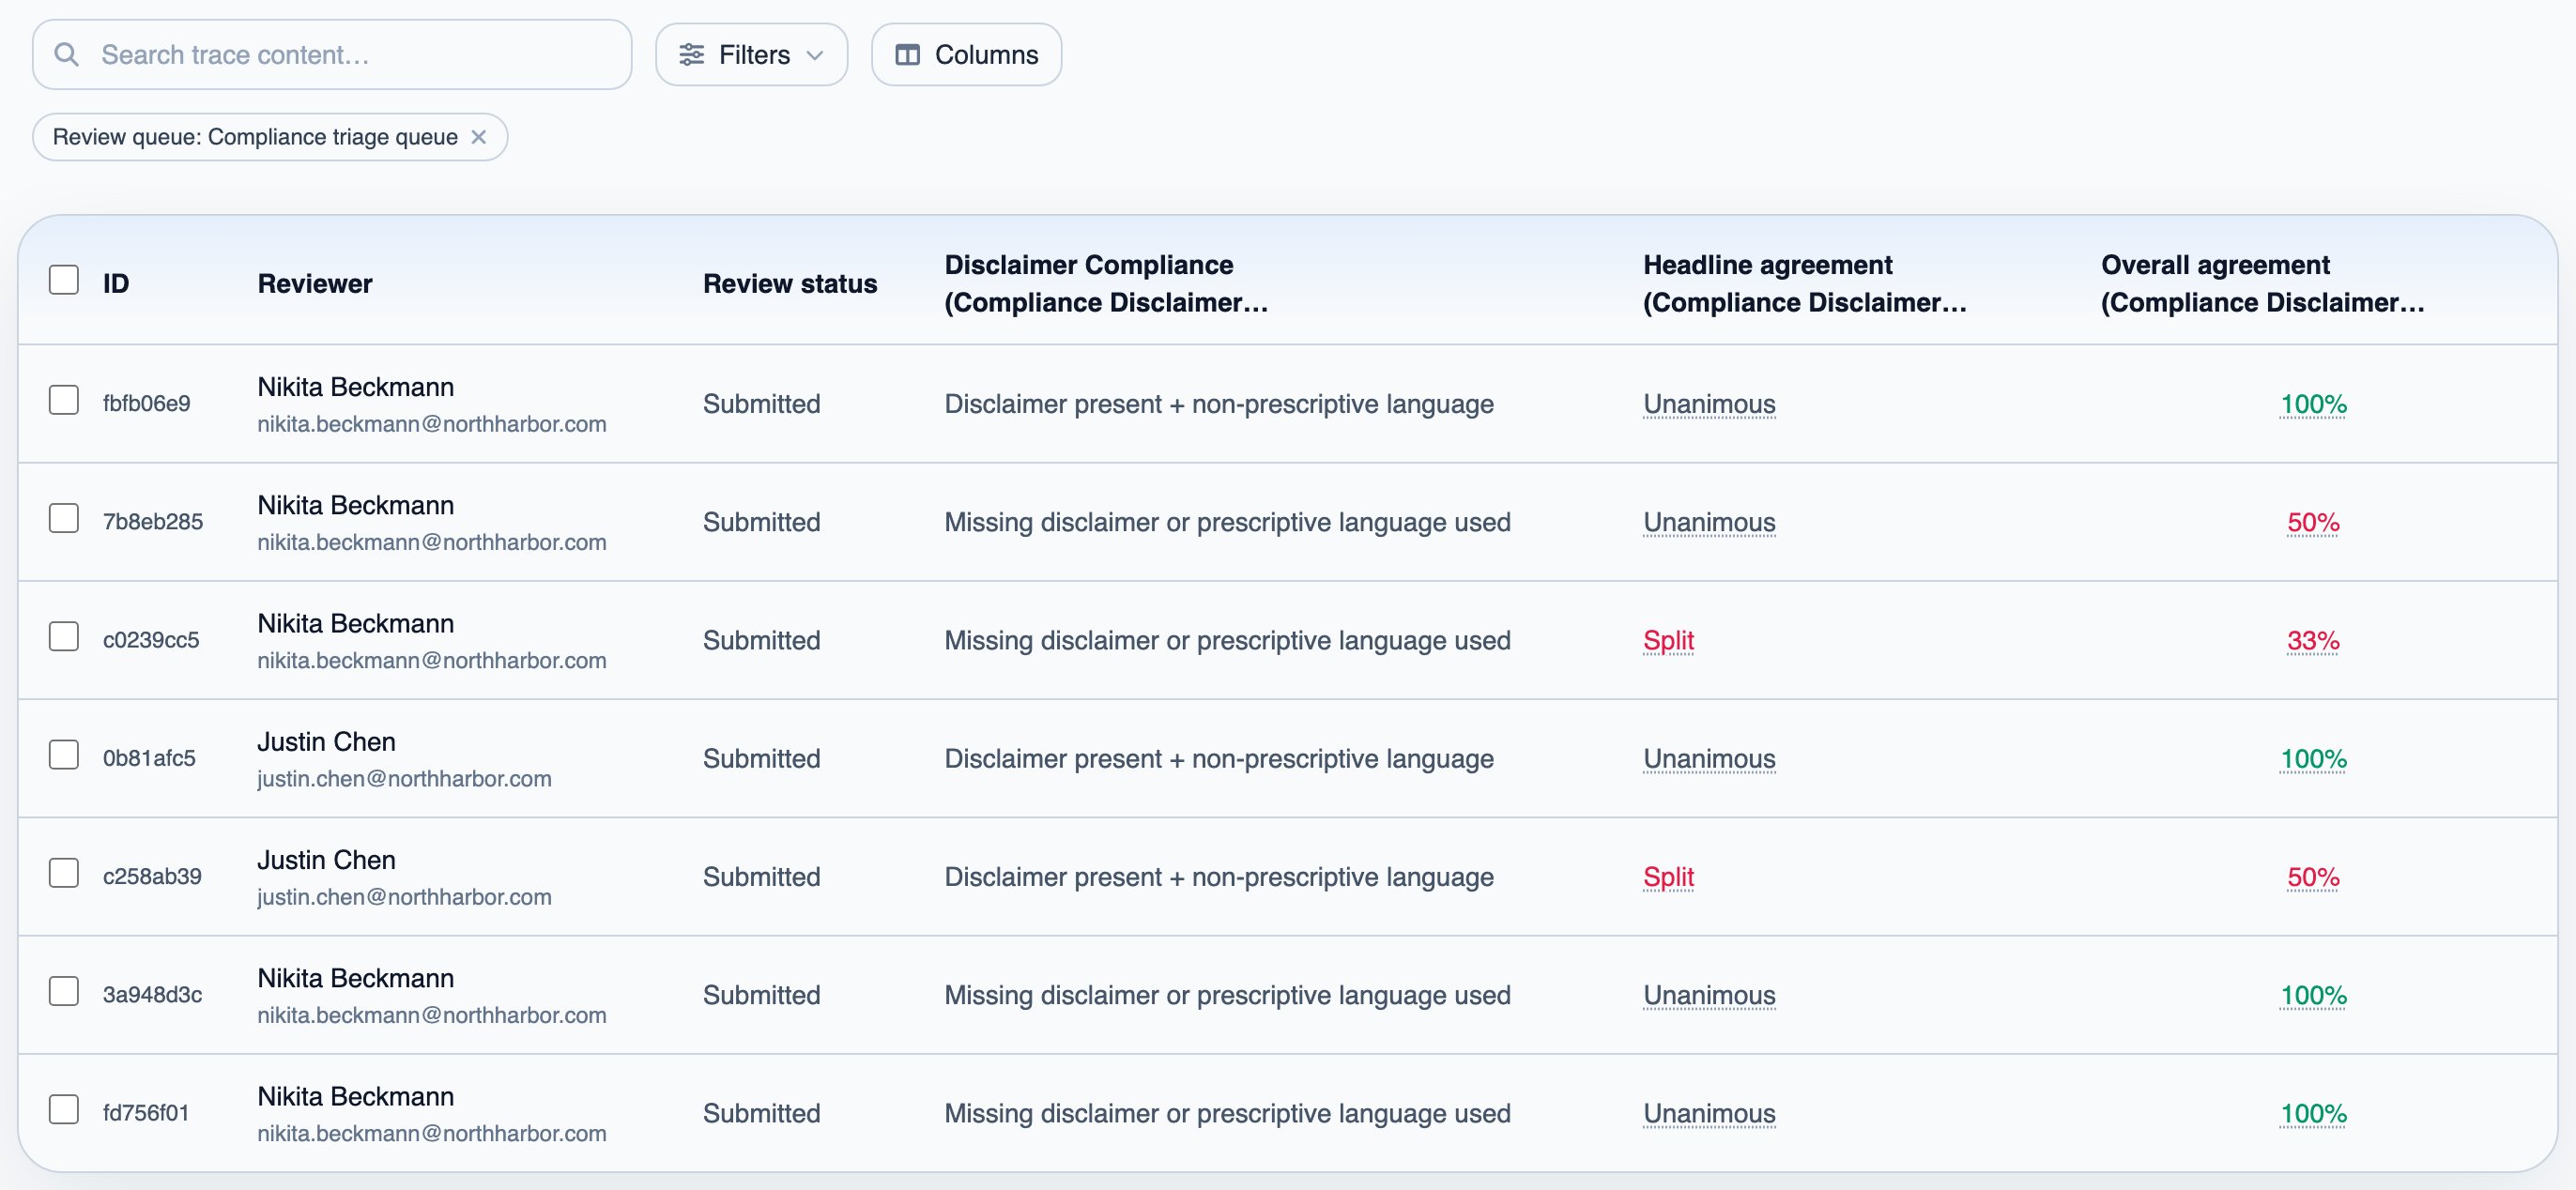
**All Reviews** lists every review across all reviewers. When more than one reviewer grades the same trace, their grades combine into a **team verdict**, and the list shows whether they were unanimous or split on the headline dimension and how much they agreed overall.
 ## Feedback gets reused
After each submission, DataFramer distills what the reviewer decided, and why, into **memory**. The Review Copilot reads that memory on later reviews of similar traces.
From **All Reviews**, select any reviewed traces and press **Add to dataset** to make them an [evaluation dataset](/docs/judges/datasets-and-evaluations) for calibrating a judge, or a [generation seed dataset](/docs/concepts#where-seed-data-comes-from) so the cases your experts just corrected seed the next batch of synthetic data.
## Next steps
Calibrate a judge against this review data
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.