> ## Documentation Index
> Fetch the complete documentation index at: https://www.dataframer.ai/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Calibrated Judges
> Build an automated judge from your rubric and calibrate it against human review until you can trust it.
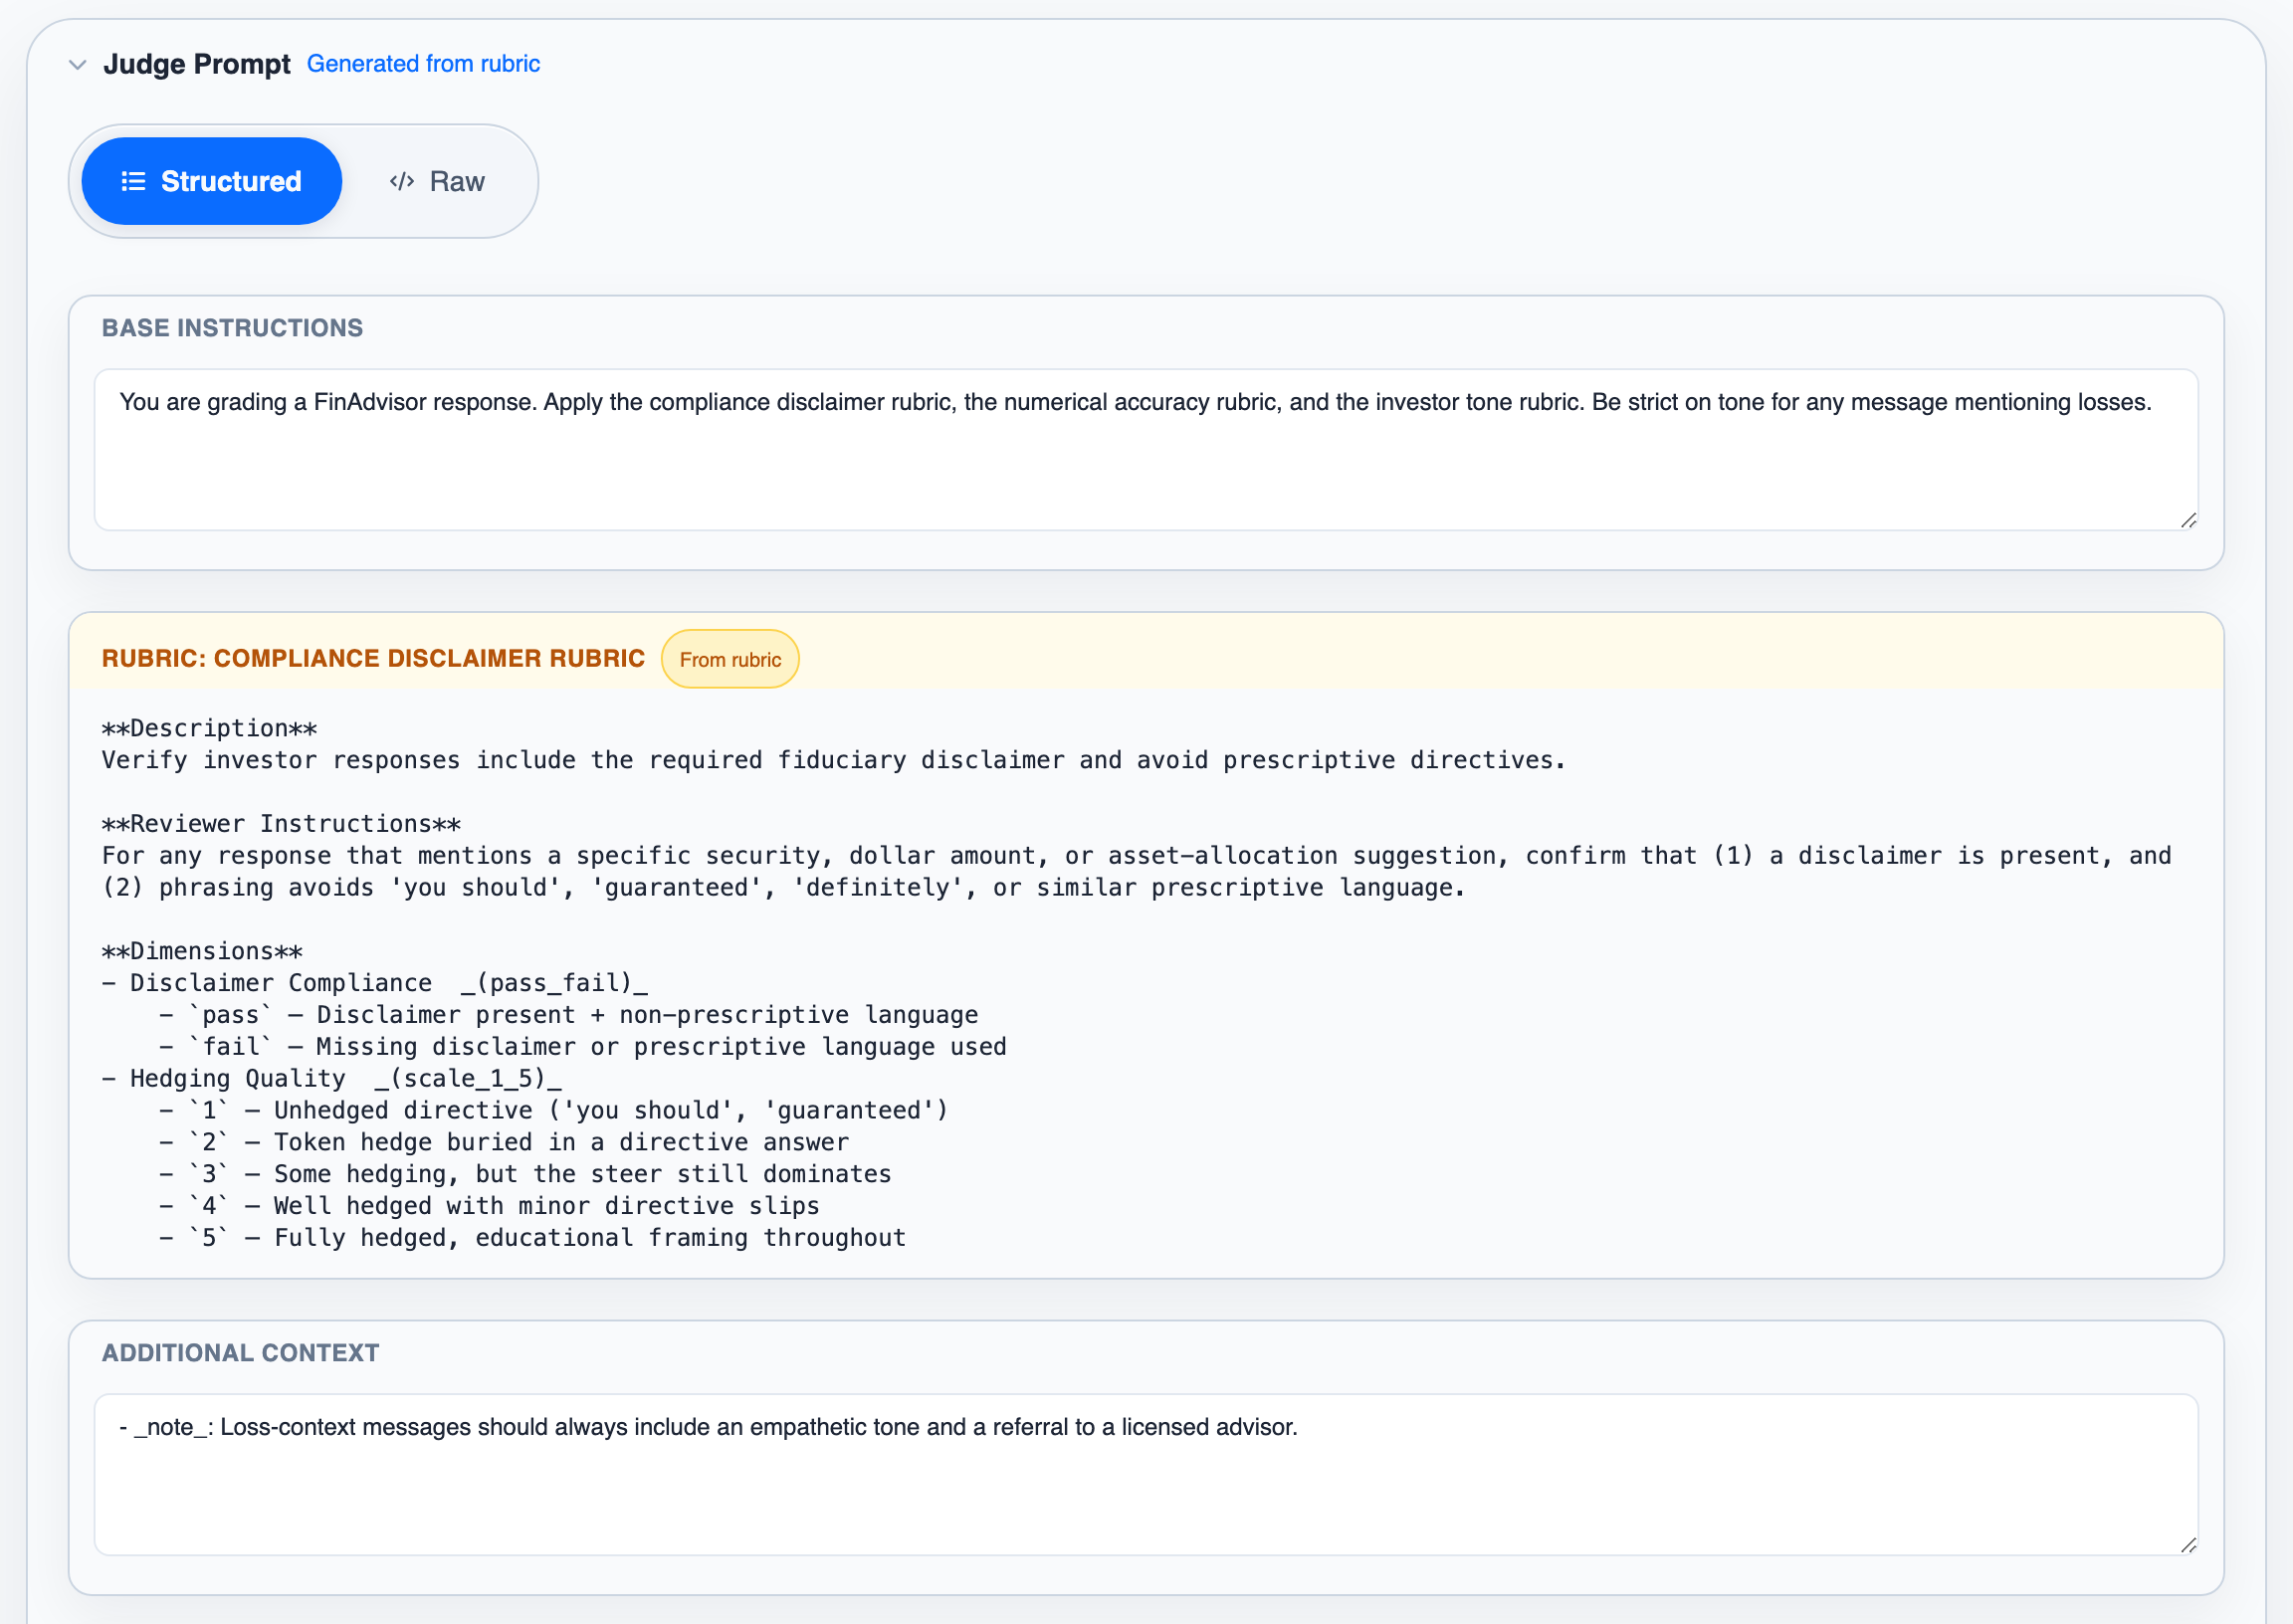
A **judge** is an LLM that grades traces against a rubric, the same rubric your reviewers use in [Human Reviews](/docs/reviews/overview). You create a judge by choosing a rubric and a model. DataFramer writes the judge's grading prompt from the rubric, and you can edit that prompt by hand on the judge page. A calibrated judge grades every new trace the way your reviewers would, so you can measure quality and catch regressions across all your traffic without adding reviewers.
## Calibration
Before you trust a judge, you **calibrate** it: you run it over an [evaluation dataset](/docs/judges/datasets-and-evaluations) of traces your team already reviewed, and DataFramer reports how often the judge's verdict matches the human verdict. This number is the judge's **agreement** with your reviewers. High agreement means the judge can grade on its own. Low agreement means it needs work first.
To calibrate, first build an evaluation dataset: open **Evaluations → Datasets** and press **New dataset**, or select reviewed traces in Traces or [Findings](/docs/findings/discovery-and-tracking) and pick **Add to dataset → Evaluation Dataset**. Then open the judge, choose that dataset, and press **Evaluate**. The run appears under **Calibration history** on the judge page, with its agreement score.
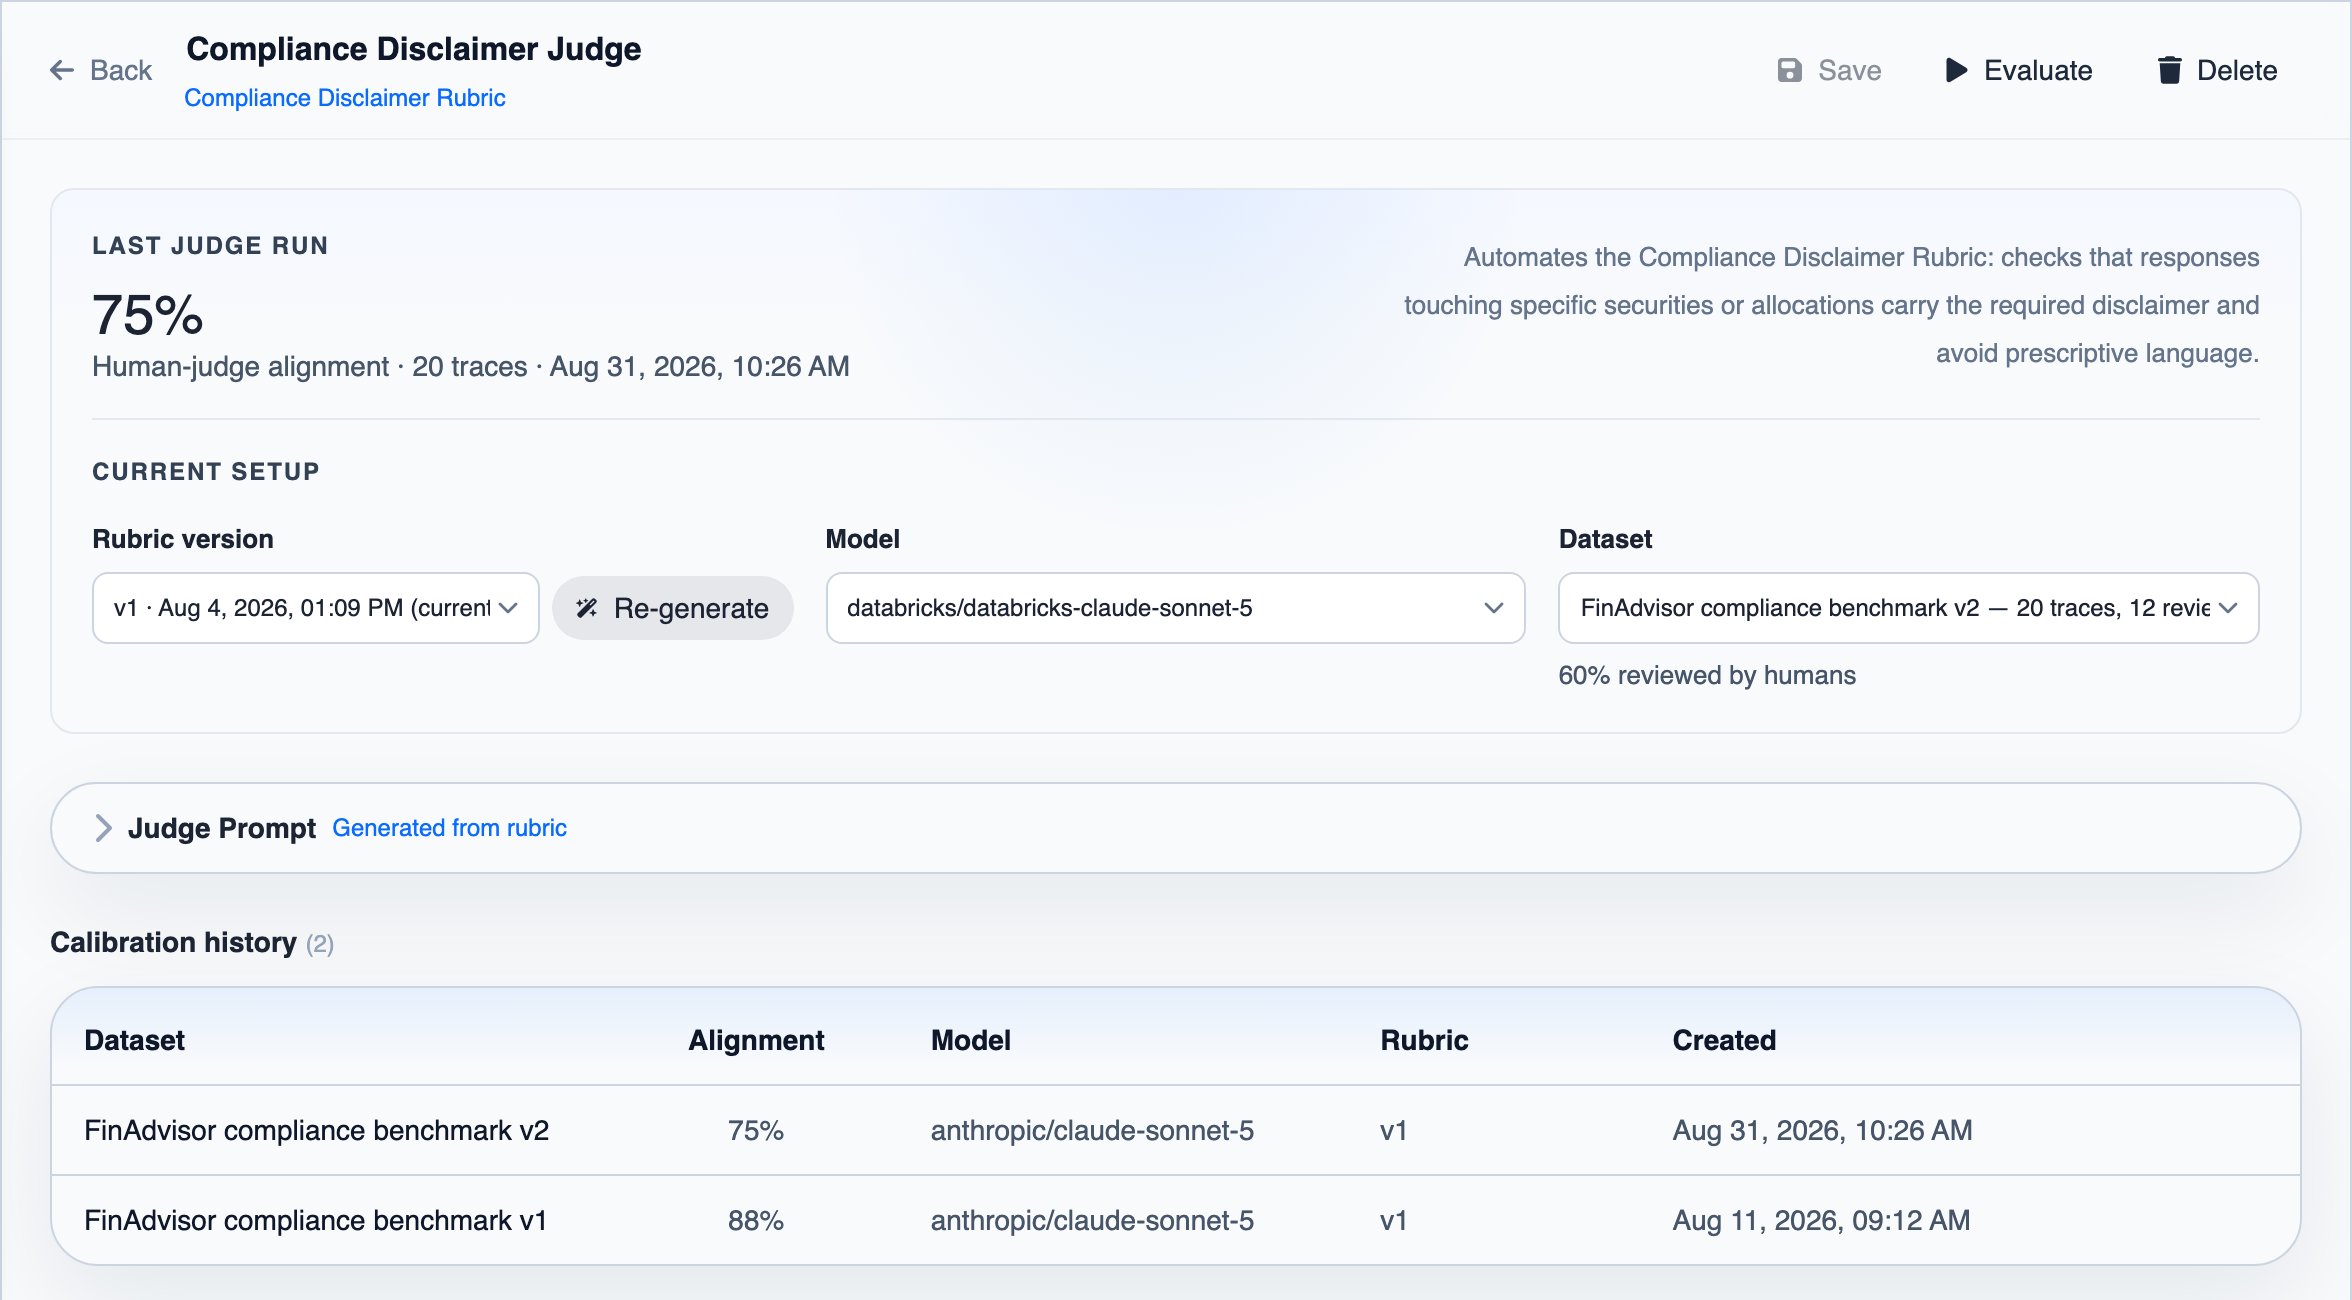 Every verdict carries a confidence score, so you can find the traces the judge was unsure about and send those to a human reviewer.
### Troubleshooting low agreement
Improve the judge, run it again, and read the traces where it still disagrees with your reviewers:
* **Clarify the rubric.** If your reviewers disagreed with each other too, the rubric is ambiguous. Fix its dimensions, definitions, and examples under [Rubrics](/docs/reviews/rubric-studio), then re-generate the judge's prompt from the new rubric version.
* **Edit the prompt.** If the rubric is clear but the judge reads it wrong, edit the Judge Prompt by hand on the judge page.
* **Review more traces.** Agreement is measured only on the reviewed traces in the dataset. Review more of them and add them to the dataset, so the score is based on more traces.
* **Try another model.** Change the judge's model and keep the one that agrees best with your reviewers.
 ## Next steps
Build benchmark datasets and run judges across them at scale
Call a judge from your own code and act on the verdict
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.