> ## Documentation Index
> Fetch the complete documentation index at: https://www.dataframer.ai/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Dataset evaluations
> Build benchmark datasets of real traces and run a judge across them.
Once a judge is [calibrated](/docs/judges/overview), you can use it to score many traces at once: put the traces in a dataset, run the judge over it, and read the results per dimension and per trace.
## Datasets
An **evaluation dataset** is any set of traces you want a judge to score: last week's traffic, a regression set, or one failure pattern. Create one under **Evaluations → Datasets** with **New dataset**, or select traces in Traces or [Findings](/docs/findings/discovery-and-tracking) and pick **Add to dataset → Evaluation Dataset**, so a failure you found there becomes a dataset.
## Evaluations
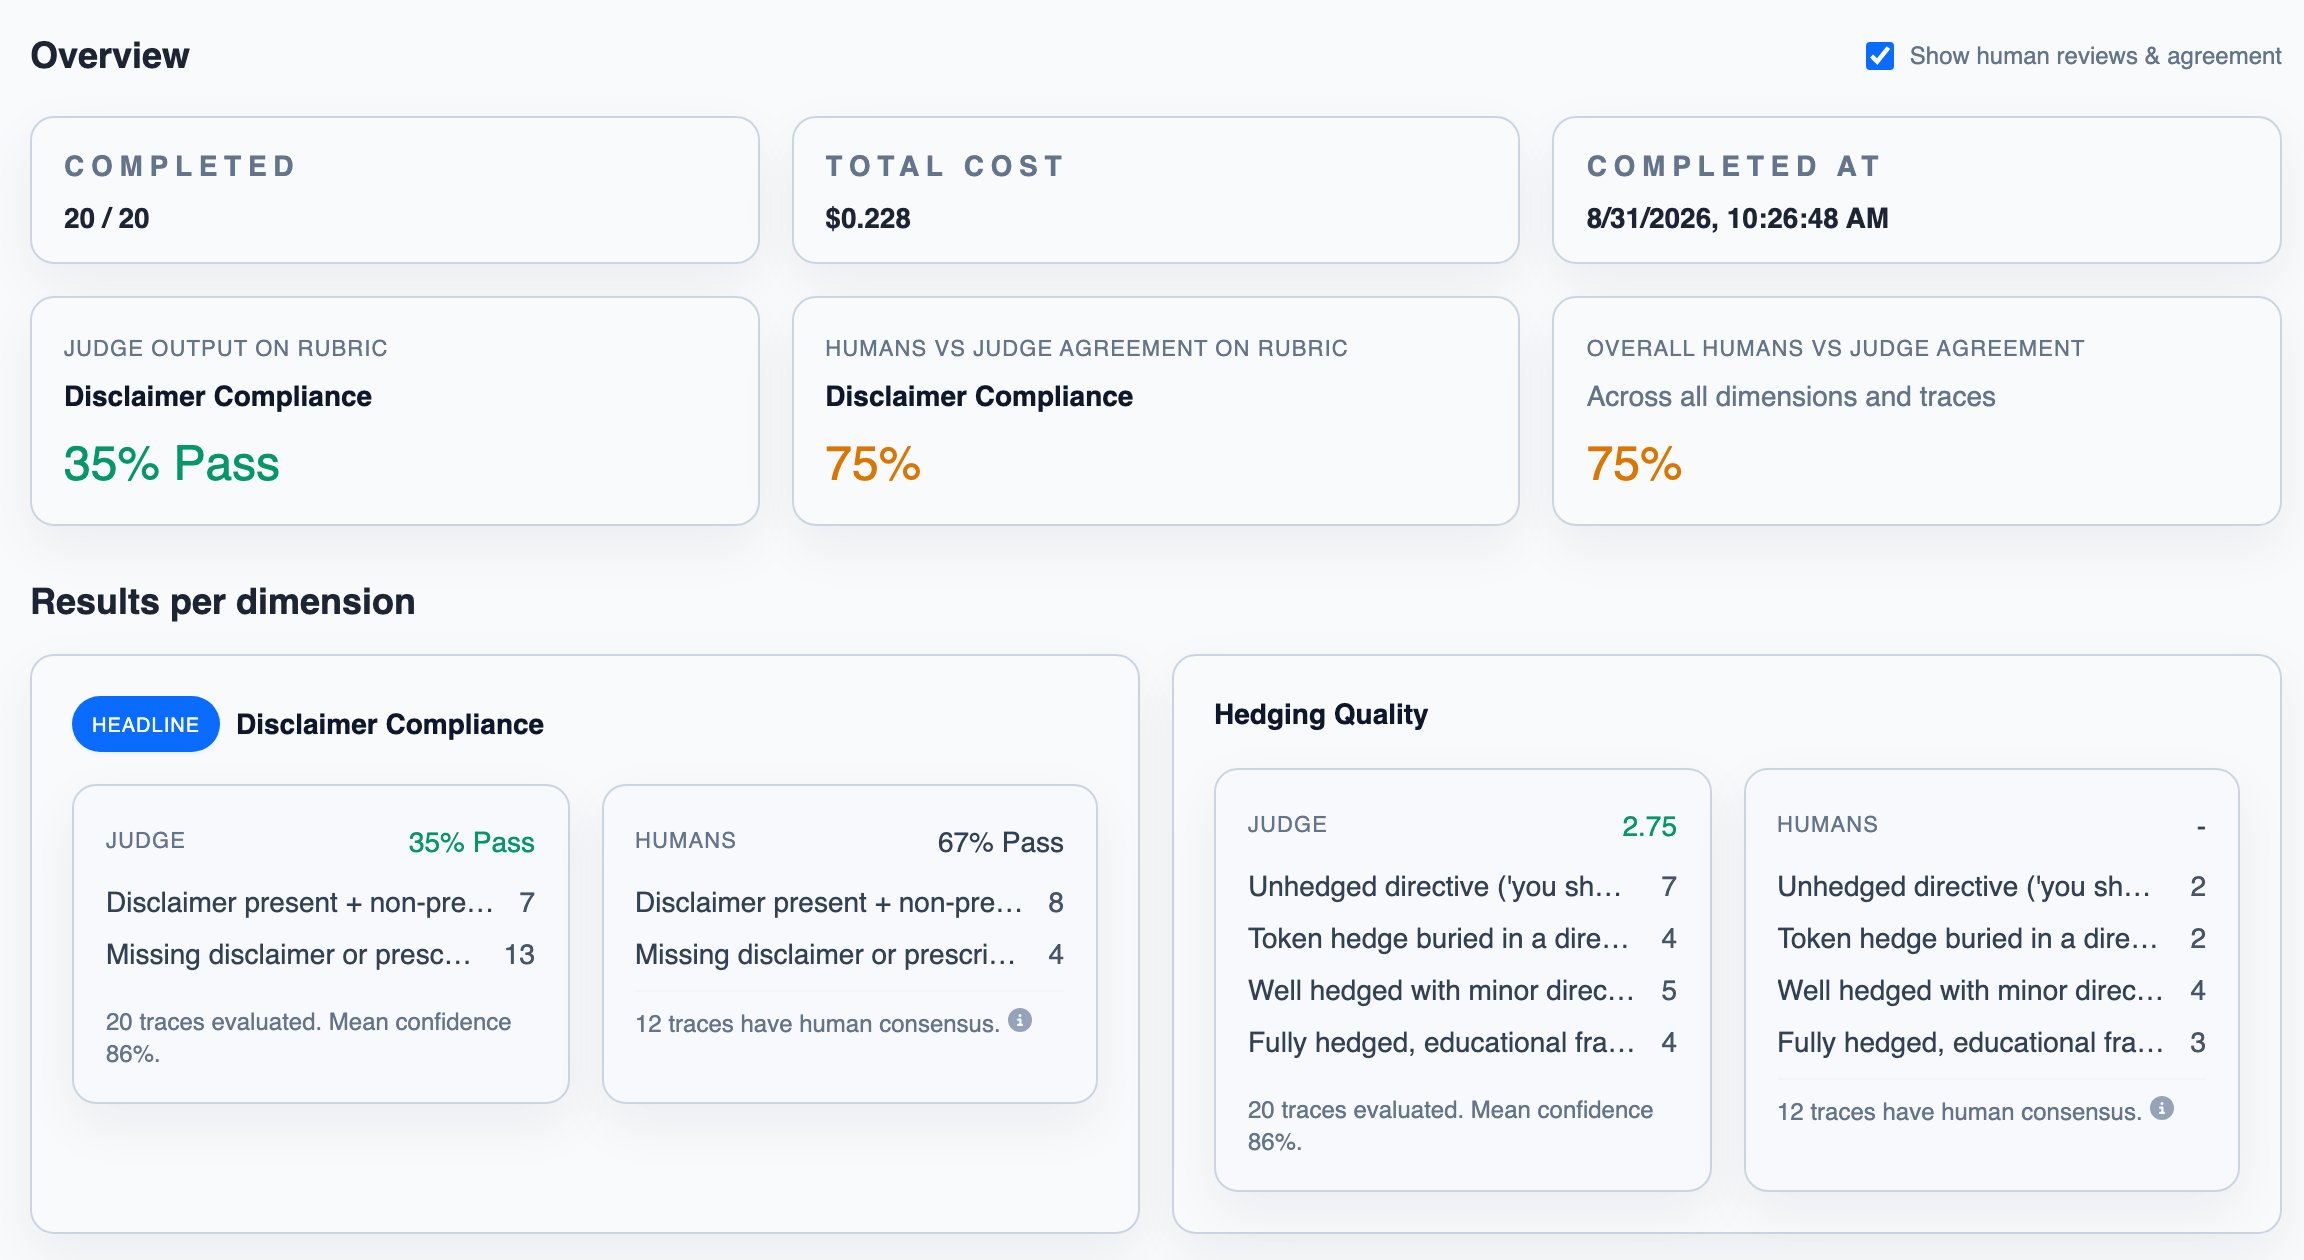
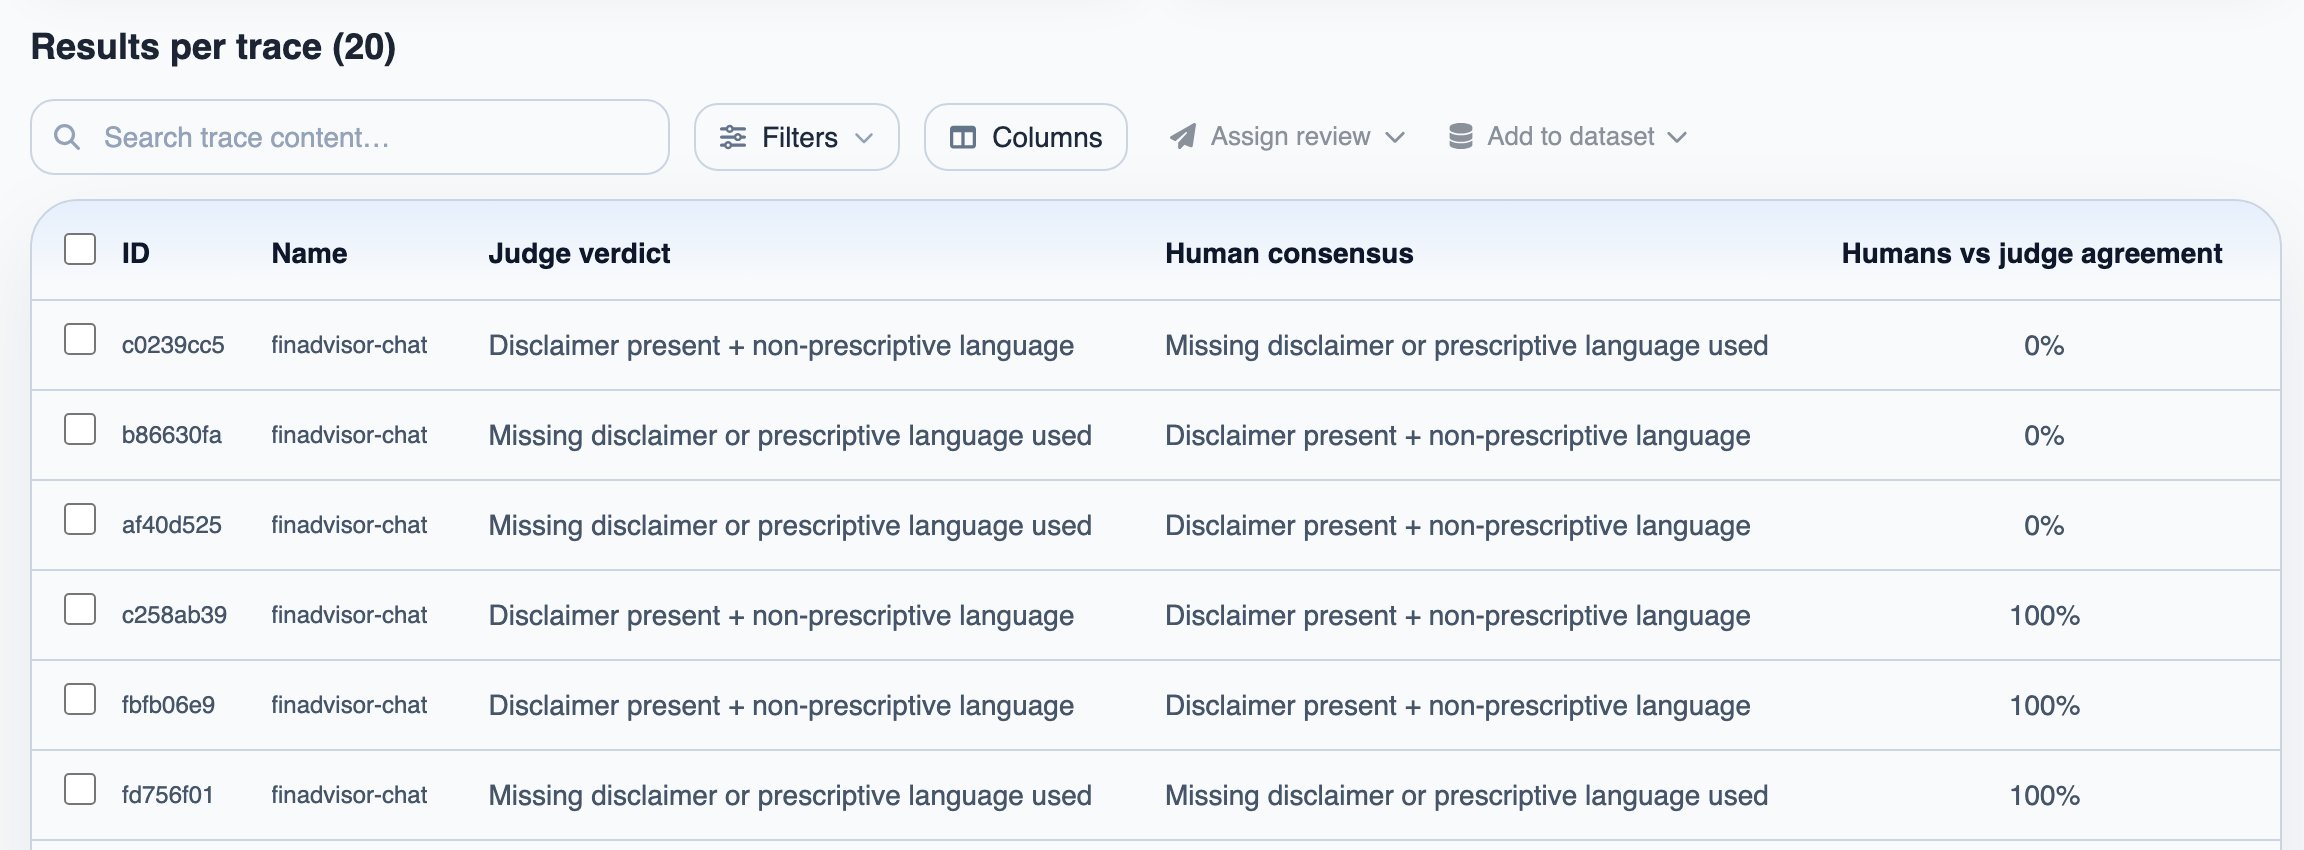
An **evaluation** runs a judge across a dataset and scores every trace. Start one under **Evaluations** with **New Evaluation**: pick the dataset, then the judge. Results break down per rubric dimension, and you can open each trace to see the details. If some traces in the dataset were reviewed by your team, each judge verdict is shown next to the human consensus.
 ## Generating data to evaluate against
To cover more cases, use real traces as seeds for [synthetic generation](/docs/concepts): select rows on the dataset page or on an evaluation's per-trace results, pick **Add to dataset → Generation Seed Dataset**, and generate additional inputs for regressions and rare edge cases from them. The traces where your judge and reviewers disagreed can seed the next generation run directly. Run the generated inputs through your app and review the resulting traces, so they join your reviewed datasets as new benchmarks. Generation also has a public API and Python SDK.
See [Core Concepts](/docs/concepts) for how seed data, specs, and generation work, and [API & MCP](/docs/api-and-mcp) for the SDK.
## Next steps
Call a judge from your own code and act on the verdict
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.