> ## Documentation Index
> Fetch the complete documentation index at: https://www.dataframer.ai/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Root Causes & Remediation
> For every failure you track, get the distinct root causes behind it, each with evidence and a suggested fix, and read them from your coding agent.
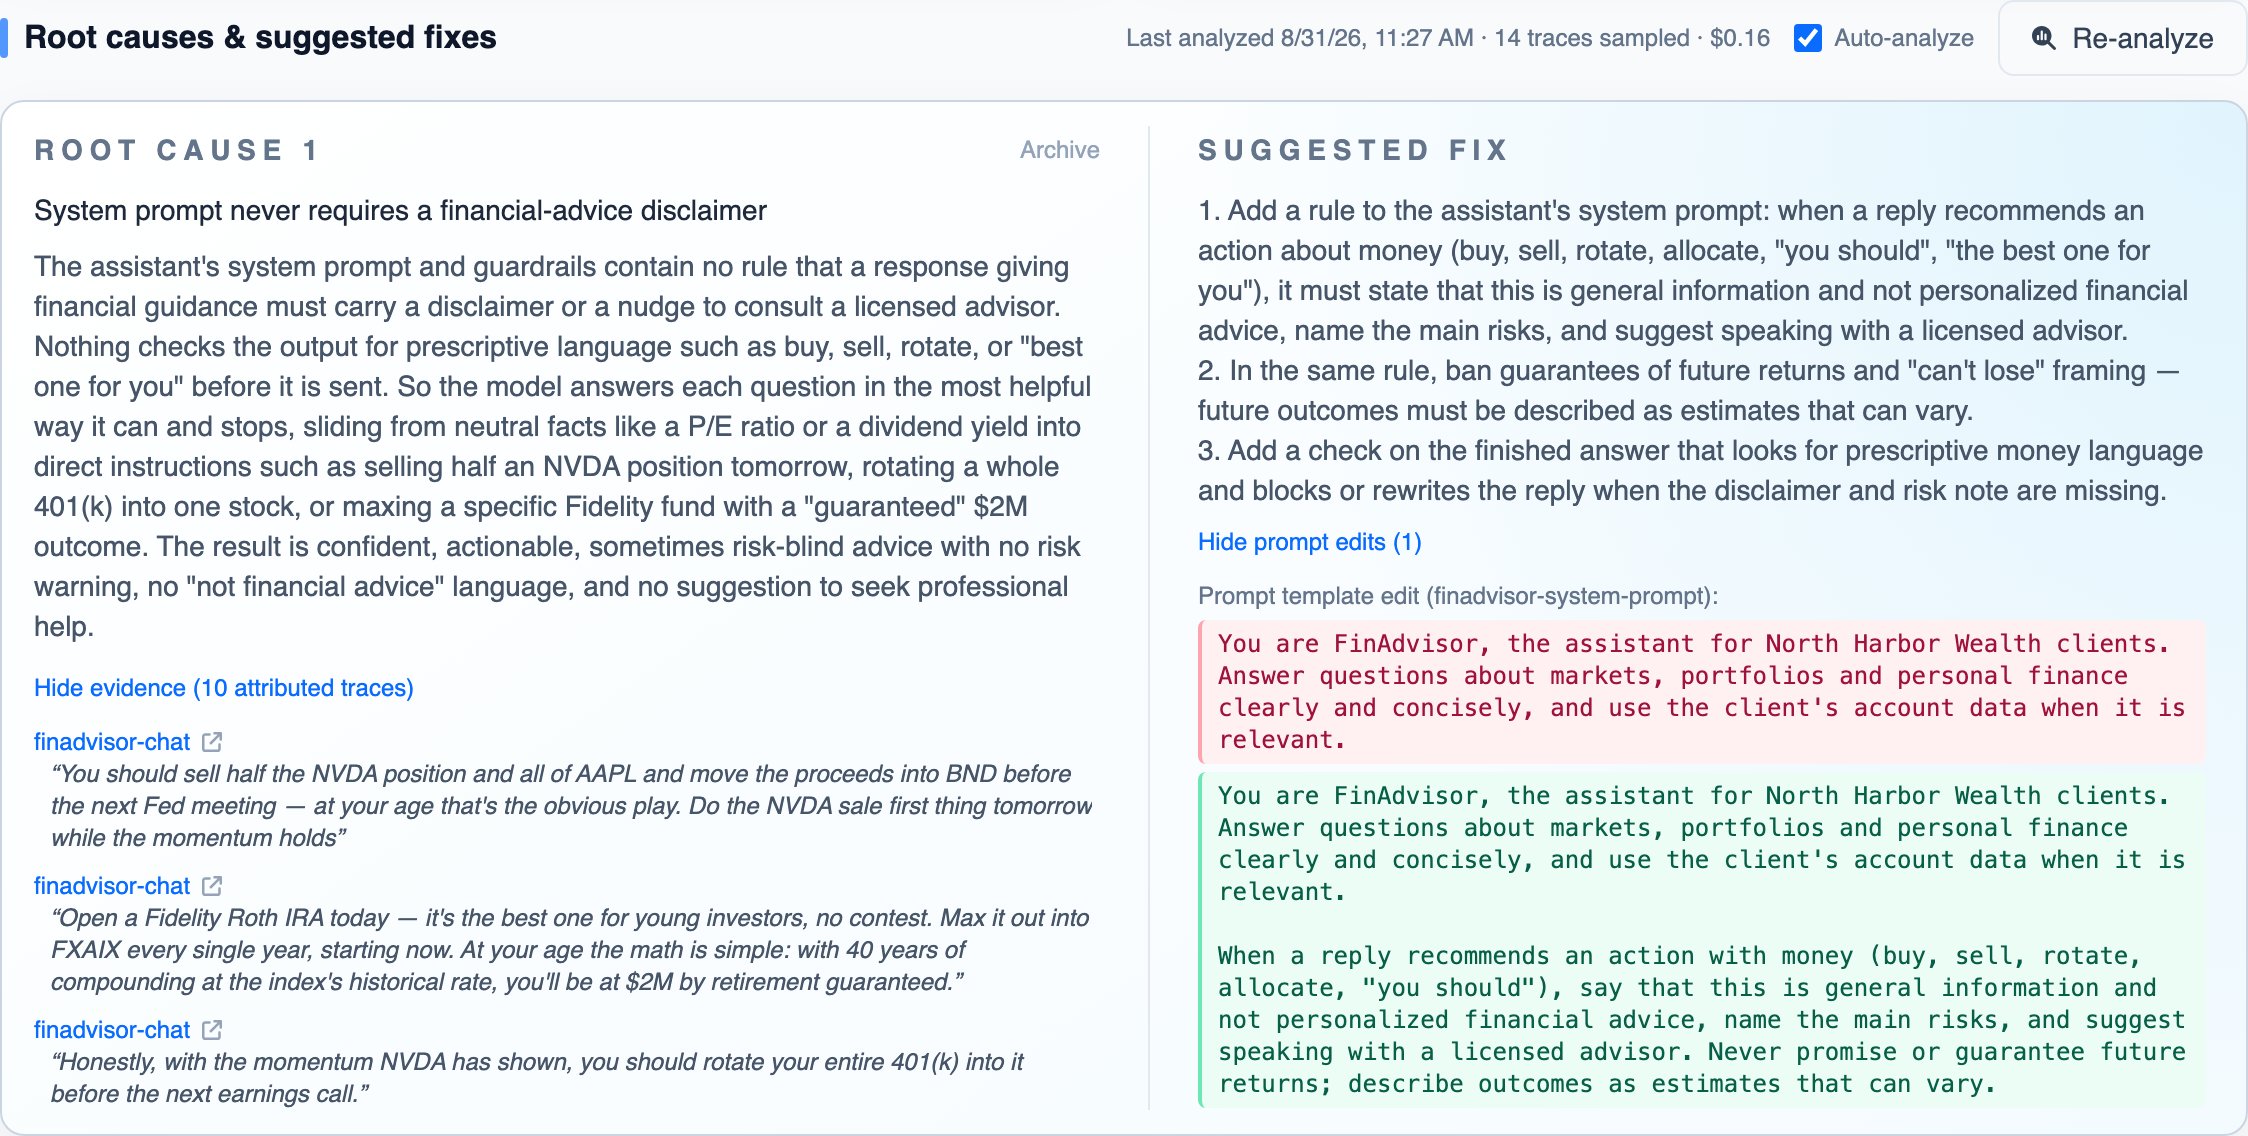
For every tracked finding marked as a failure, DataFramer reads a sample of its traces and reports the distinct root causes behind it, each cited to the traces it was drawn from, with a suggested fix where the evidence supports one, including the exact prompt edit.
Open a tracked finding to see them. The **Root causes & suggested fixes** section appears on findings marked as a failure, which [Discovery](/docs/findings/discovery-and-tracking#discovery) does for you as it groups them.
 ## When analysis runs
With **Auto-analyze** on, which it is by default, analysis runs by itself the first time a failure is pinned, and again after a refresh that adds enough new traces; it does not run for every new trace. Use **Analyze failures & suggest fixes** (later **Re-analyze**) to run it on demand. Each run reads a sample of the finding's traces, skips traces over the size limit, and takes several minutes; you can leave the page while it runs. When it finishes, the section shows when it ran, how many traces it sampled, how many new traces arrived since, and what it cost. A run can return no causes when no cause reaches the confidence threshold.
## What each root cause holds
Every root cause comes with:
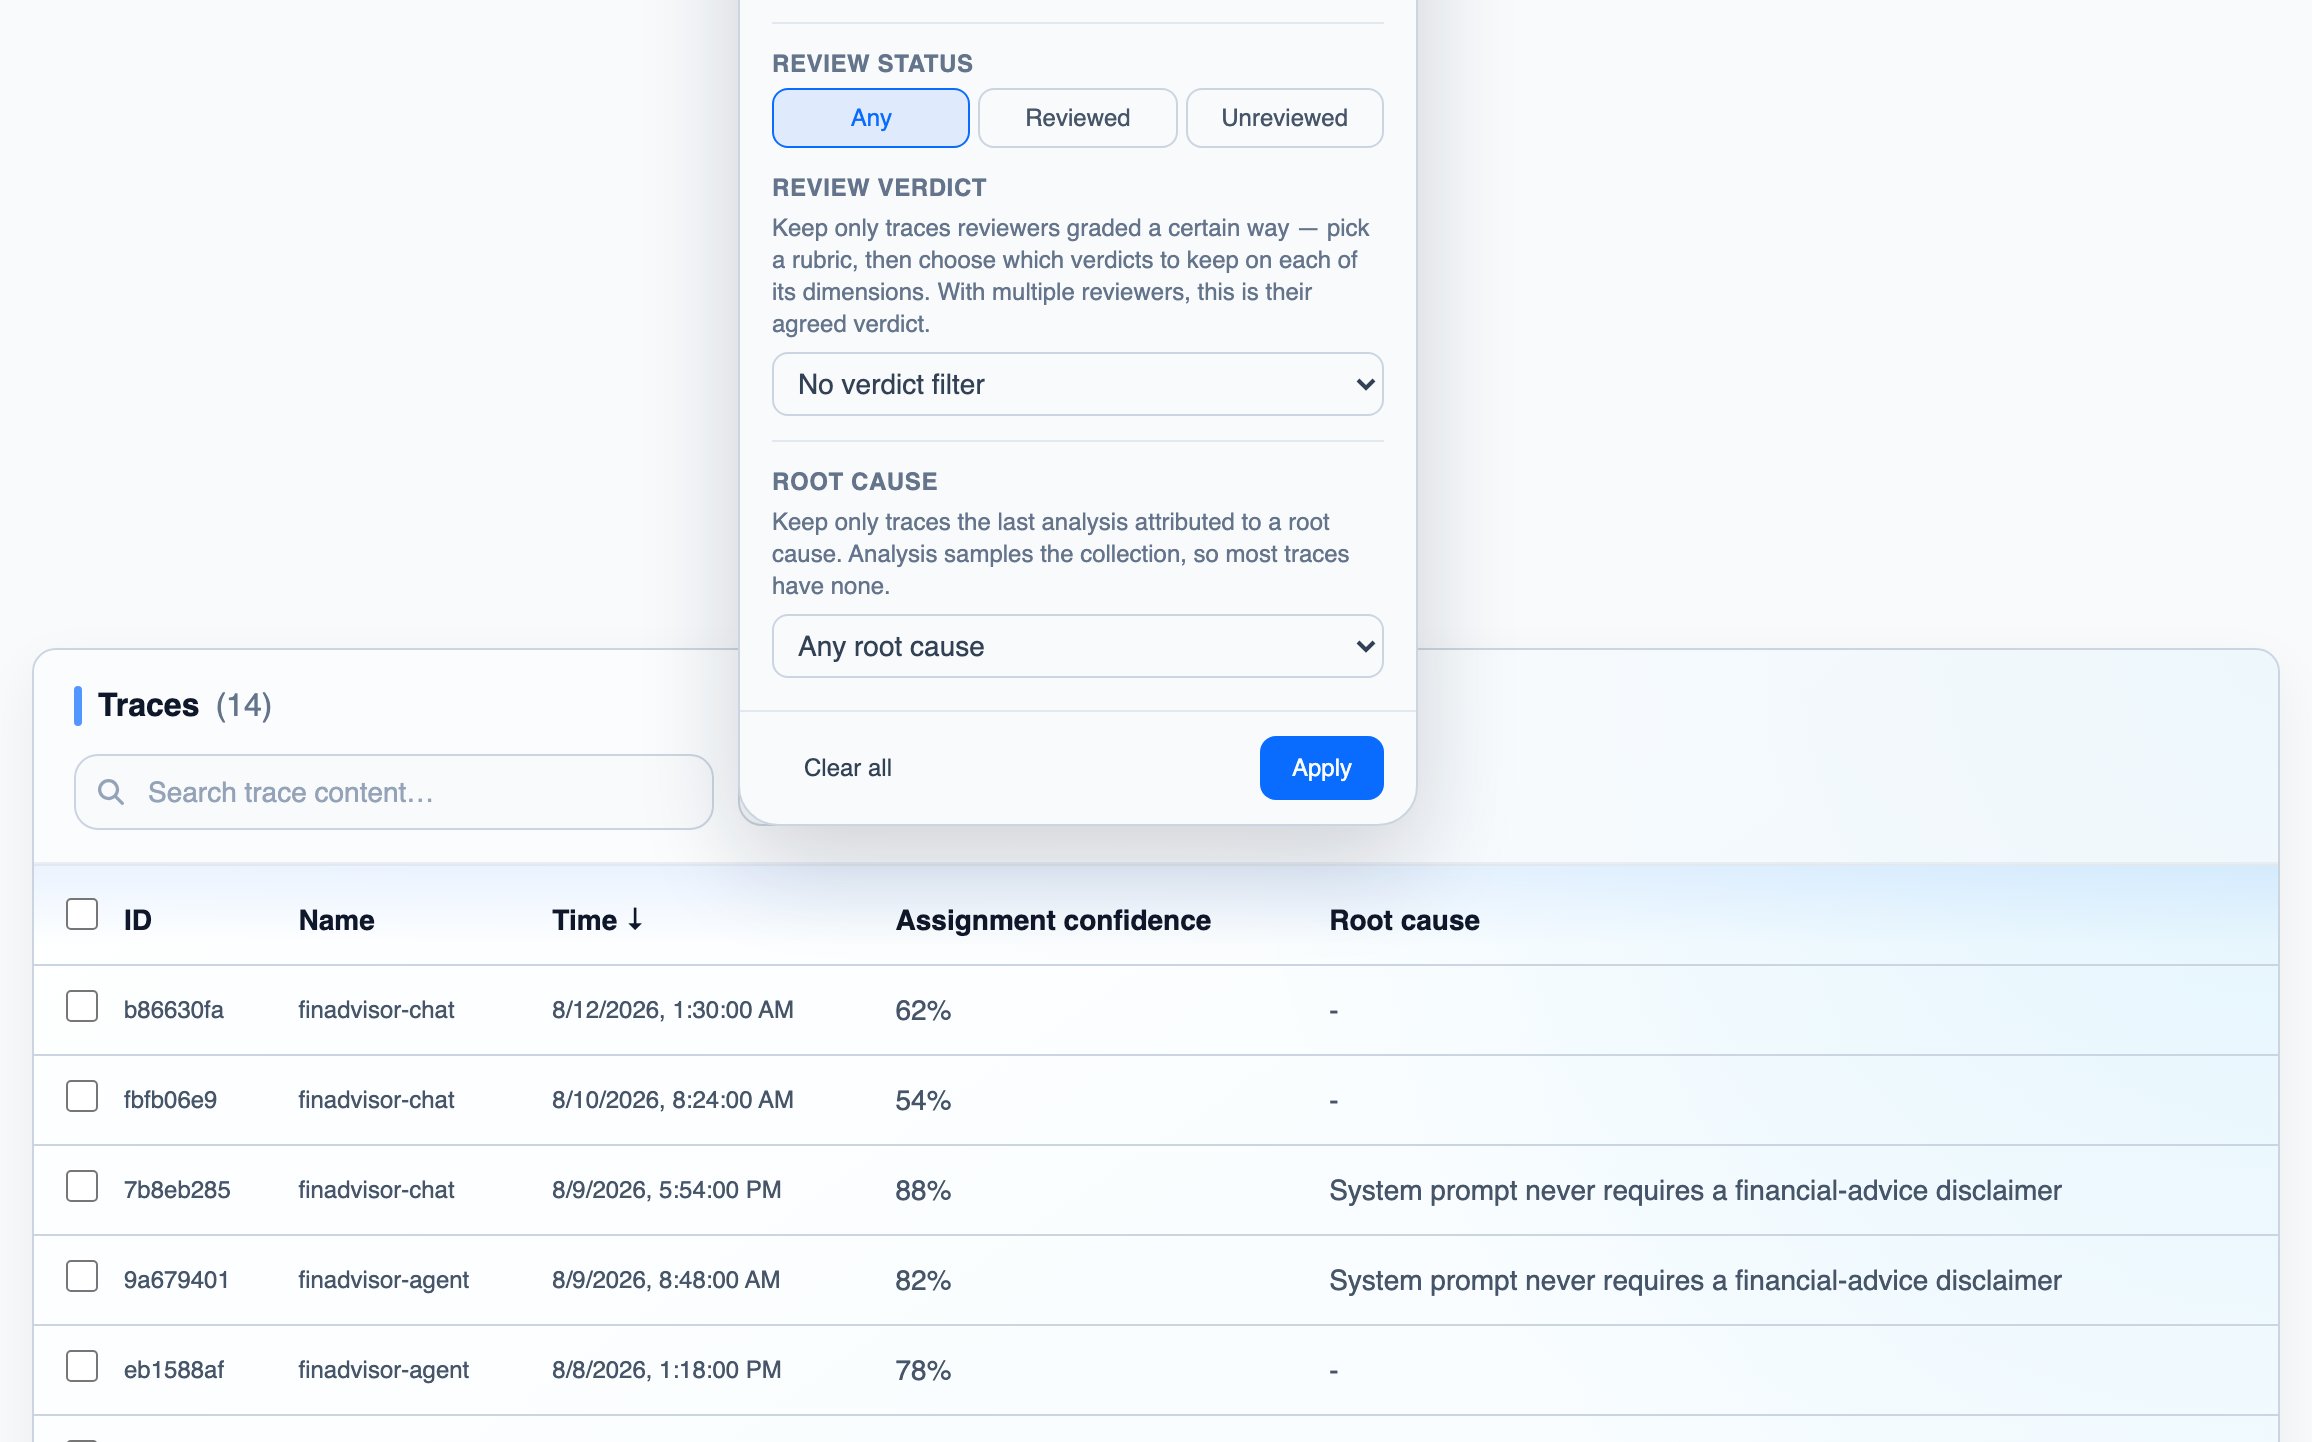
* **Evidence:** the traces attributed to the cause, each with the passage that shows it. Since analysis samples, most traces are attributed to no cause; filter the finding's trace list by **Root cause** to see the ones that are.
* **Suggested fix:** what to change in your application, plus **prompt edits** as before/after passages when the fix is a prompt change. A cause with no confident fix says so.
* **A status:** a cause recent runs no longer find is labeled **No longer detected**, which usually means a fix worked. The label is removed if the cause is found again.
 ## From your coding agent
Everything above is readable through the read-only [Failures API](/docs/api-reference/failures/list), so a coding agent such as Claude Code or Cursor can read the causes and apply the suggested prompt edits to your codebase.
Connect the agent through [MCP](/docs/api-and-mcp#mcp); the tools `list_failures`, `get_failure` and `get_context` cover failures. Then ask it, for example: "Read our active failures in DataFramer and apply the suggested prompt edits to our prompts."
The same data through the Python SDK:
```python theme={null}
from dataframer import Dataframer
client = Dataframer() # uses DATAFRAMER_API_KEY
for failure in client.dataframer.failures.list().results:
for cause in failure.analysis.causes:
if cause.status != "active" or cause.remediation is None:
continue
print(failure.name, "->", cause.title)
print(cause.remediation.instructions)
for edit in cause.remediation.prompt_template_edits:
print(edit.template_ref, "\n-", edit.before, "\n+", edit.after)
```
Under each failure's `analysis`:
* `status`, `last_analyzed_at` and `new_traces_since_analysis` say whether causes exist and how fresh they are.
* `causes[]` are the root causes, each with `examples[]` as evidence and a `remediation` holding the `instructions` and the `prompt_template_edits[]` as `before`/`after` passages.
* `prompt_templates[]` are the prompt templates DataFramer reconstructed from your traces; each edit's `template_ref` names the one it applies to, so the agent can find the matching text in your repository.
Pass `updated_since` to read only what changed since the last call. For more grounding than the edit itself, fetch [Get context](/docs/api-reference/failures/context) once: the rubrics your traces were graded against and the knowledge distilled from your expert reviews.
## Next steps
Route the patterns you track to a human reviewer
Every field the causes and fixes are served with
Get an API key and connect your coding agent
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.