> ## Documentation Index
> Fetch the complete documentation index at: https://www.dataframer.ai/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Connect your traces
> Pull your AI traces into DataFramer. No traces yet? Connect a new Langfuse or LangSmith project.
## Connect an observability tool to pull traces from
**Currently supported: Langfuse and LangSmith.** More observability tools are on the roadmap. If you do not have one yet, create a free Langfuse or LangSmith project and point your app's tracing at it.
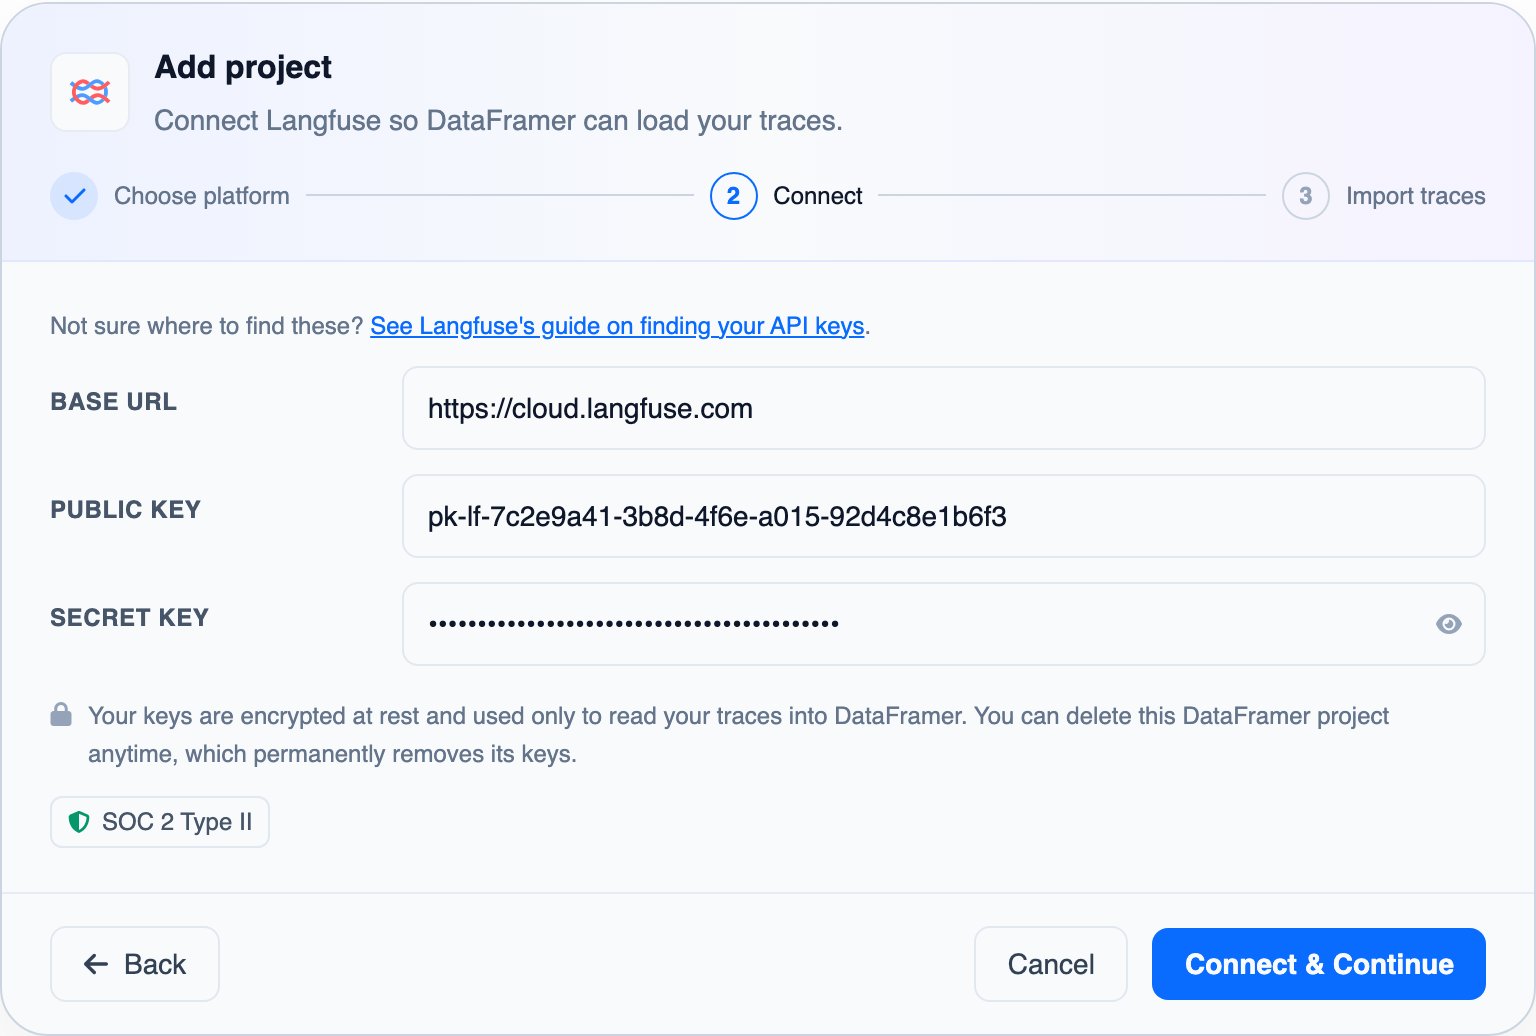
In the DataFramer UI, open the project picker at the top of the sidebar, add a project and choose your tool:
| Field | Example |
| - | - |
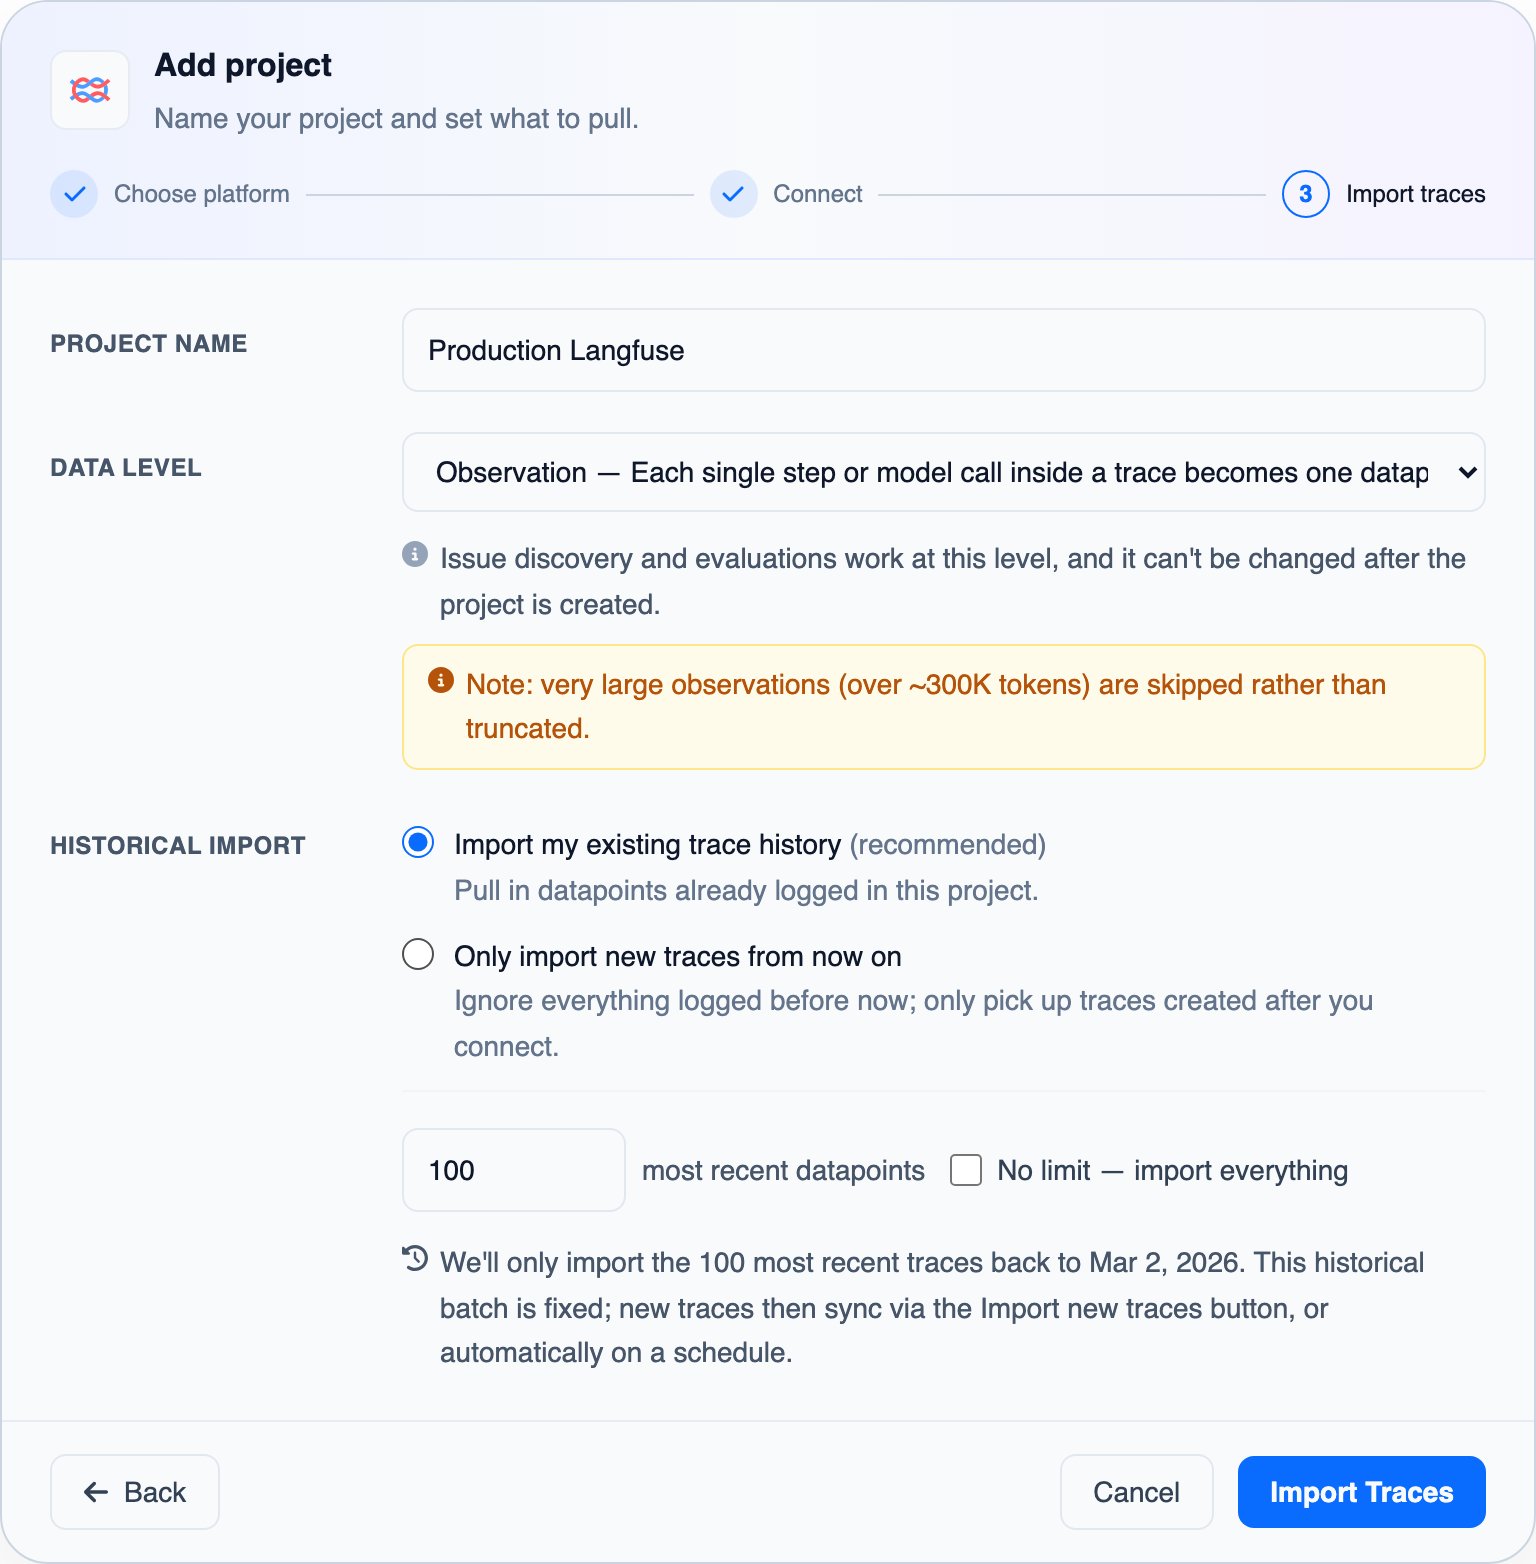
| Project Name | `My Production Langfuse` |
| Base URL | `https://cloud.langfuse.com` (default) |
| Public Key | `pk-lf-...` (from your Langfuse project settings) |
| Secret Key | `sk-lf-...` (from your Langfuse project settings) |
| Data level | `Observation` (default), `Trace`, or `Session` |
| Field | Example |
| - | - |
| Project Name | `My Production LangSmith` |
| Endpoint URL | `https://api.smith.langchain.com` (default) |
| API Key | `ls-...` (from your LangSmith account settings) |
| LangSmith Project | the project name in LangSmith to pull runs from |
| Data level | `Run` (default), `Trace`, or `Thread` |
 Once connected, DataFramer pulls your traces in. **Import new traces** on the Traces page pulls on demand; the count next to the time window says how many traces are in it and how many were skipped, and why.
Two settings are fixed once the project is created:
* **Data level** sets what one datapoint is, and discovery and evaluations work at that level. Trace- and session-level datapoints can be large (>1M tokens); those are imported and then processed in pieces. Only ones above 10M tokens are skipped at import.
* **Import history**: the traces already logged in the tool before the first import, or only the traces created from now on.
 ## See your traces
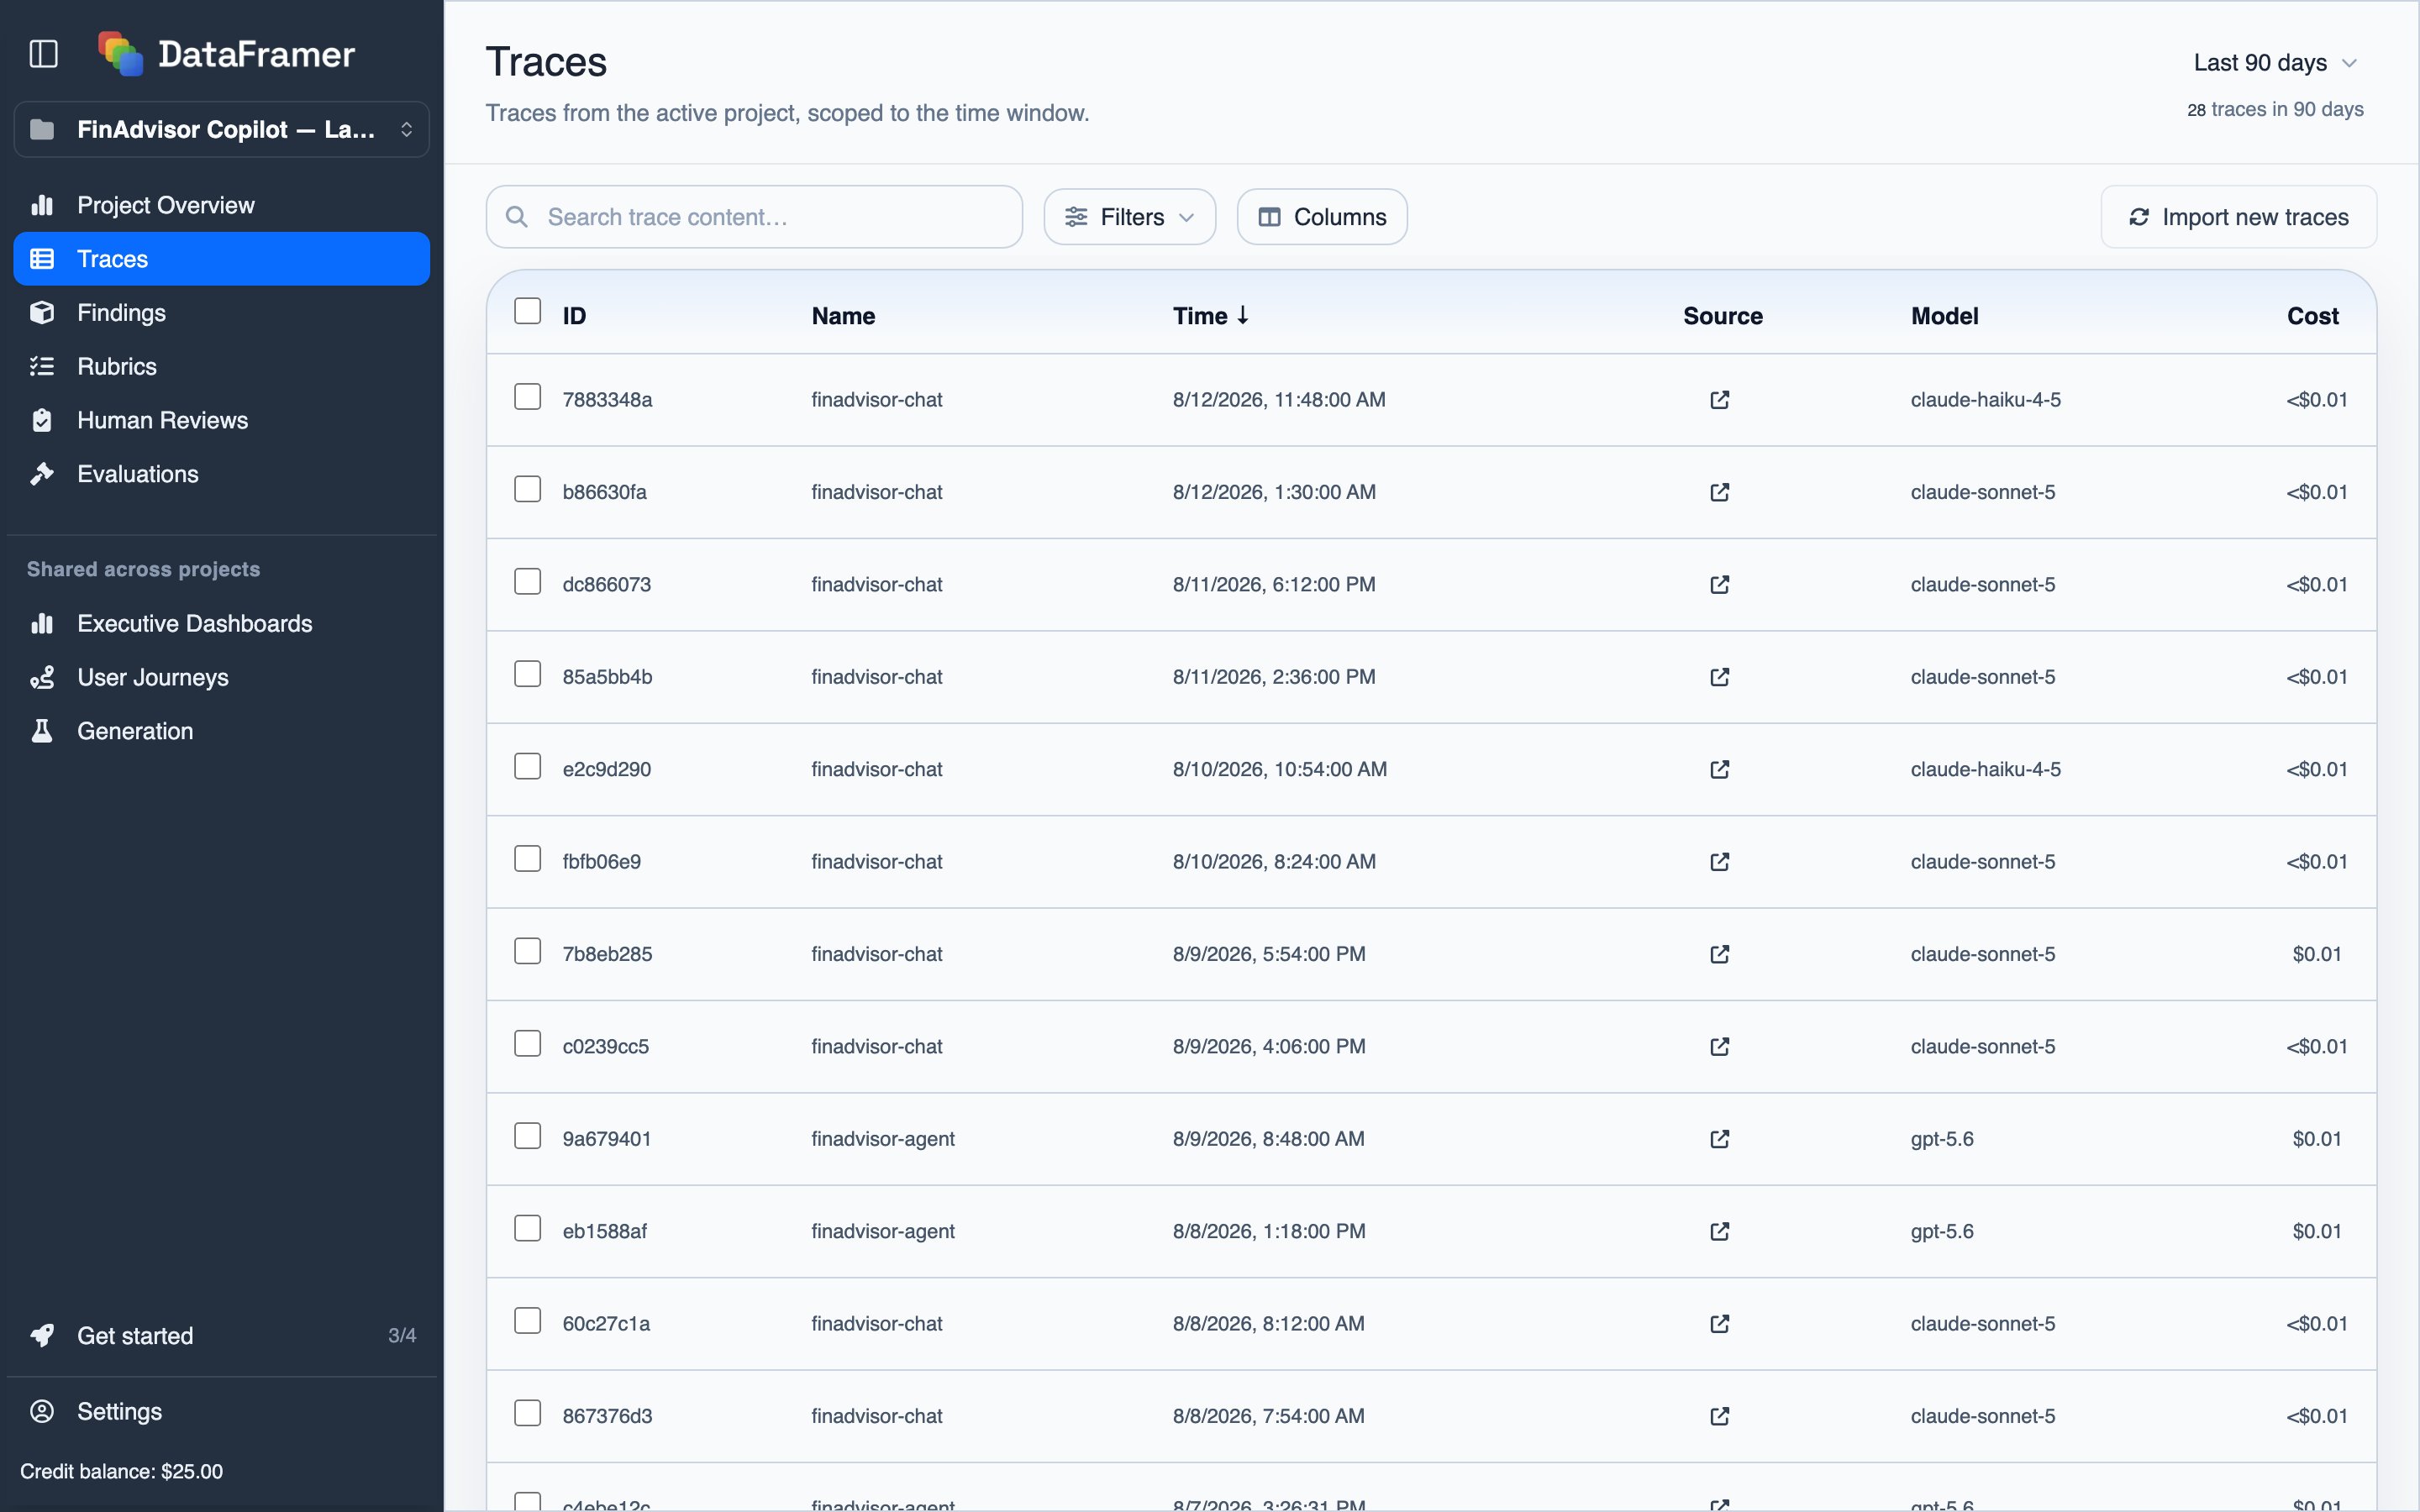
The [**Traces**](https://app.dataframer.ai/traces) page lists the imported traces for the time range you pick. Open a trace to see everything DataFramer knows about it, and use the [Review Copilot](/docs/reviews/copilot) there to ask questions with the full context around it.
 ## Route traces onward
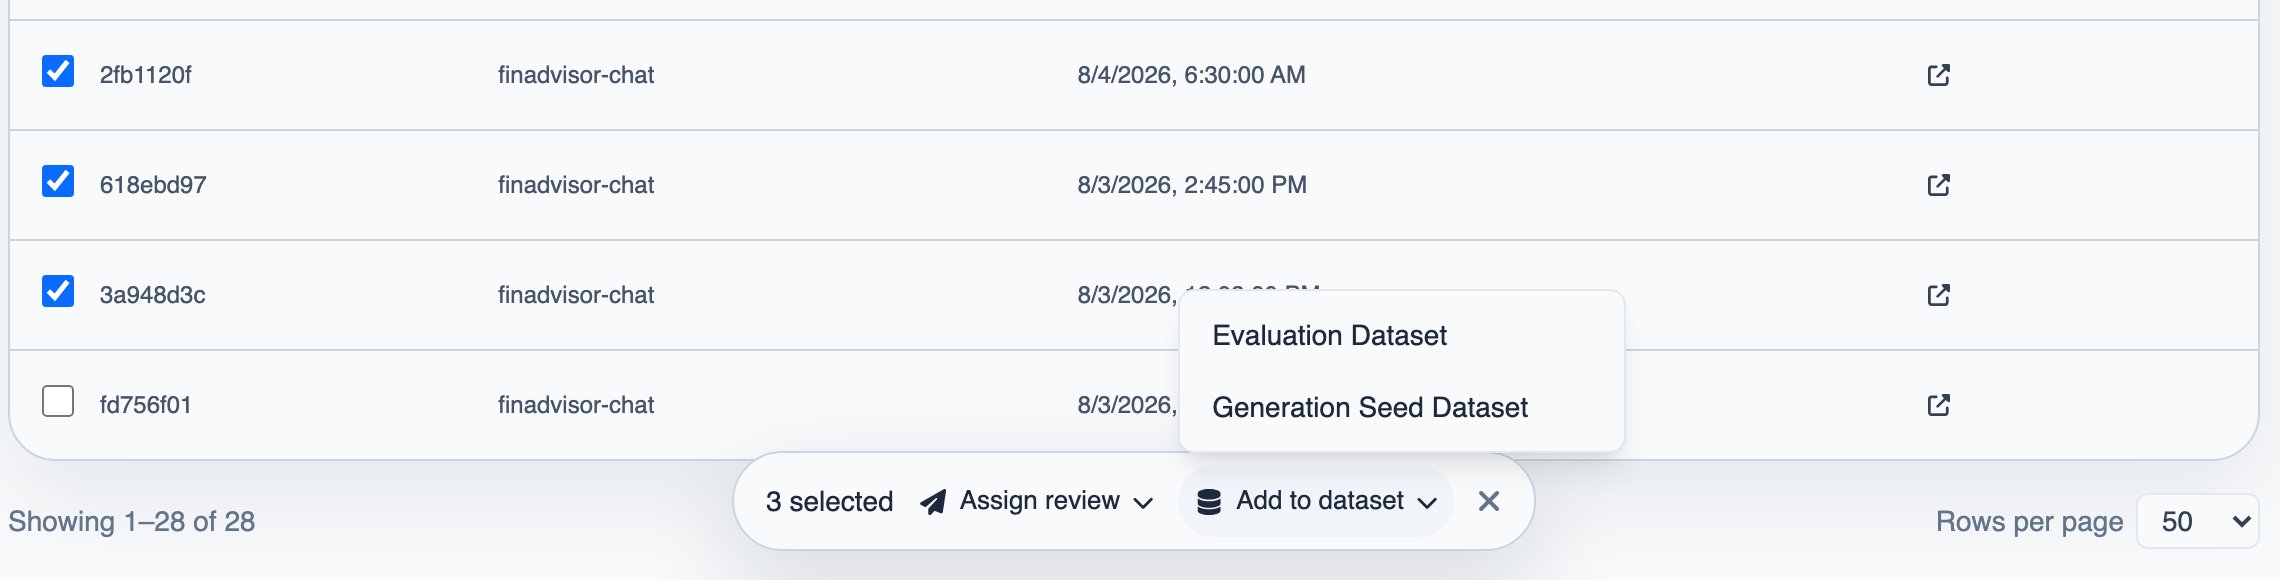
Wherever DataFramer lists traces, select any subset and route it onward: **Assign review** sends the traces to a [review queue](/docs/reviews/overview), **Add to dataset → Evaluation Dataset** makes them ground truth for [judges](/docs/judges/overview), and **Add to dataset → Generation Seed Dataset** makes them seed examples for [synthetic generation](/docs/concepts#where-seed-data-comes-from).
 ## Connect traces to user journeys
The [Signals SDK](/docs/user-signals/browser-sdk) records what your users do in your product: clicks, feedback, workflow events. To line those signals up with the AI traces that happened around them, each trace has to carry the same `journey_id` as the signals. The `dataframer-journey` library stamps it onto every Langfuse trace or LangSmith run as your service creates it; see [server instrumentation](/docs/user-signals/server-instrumentation).
## Next steps
Search your traces for patterns and track the ones that matter
Route traces to expert reviewers
Grade every trace automatically against your rubric
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.